<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="4.4.1">Jekyll</generator><link href="/feed.xml" rel="self" type="application/atom+xml" /><link href="/" rel="alternate" type="text/html" /><updated>2026-09-20T14:51:28+00:00</updated><id>/feed.xml</id><title type="html">Geoff Williams Blog</title><subtitle>Homelab, 3D printing, debugging and random notes</subtitle><author><name>Geoff Williams</name><email>geoff@declarativesystems.com</email></author><entry><title type="html">Homelab - Migrating off Rook/Ceph</title><link href="/2026/09/12/homelab-migrate-off-rook-ceph.html" rel="alternate" type="text/html" title="Homelab - Migrating off Rook/Ceph" /><published>2026-09-12T00:00:00+00:00</published><updated>2026-09-12T00:00:00+00:00</updated><id>/2026/09/12/homelab-migrate-off-rook-ceph</id><content type="html" xml:base="/2026/09/12/homelab-migrate-off-rook-ceph.html"><![CDATA[<p>In my <a href="/2026/09/10/homelab-agentic-vs-maintenance.html">previous post</a>, I decided my Rook/Ceph experiment with replicated storage is finished, and it’s time for a much simpler homelab with LVM localpv.</p>

<p>With five storage nodes using dedicated devices, I want to migrate off Ceph with zero data loss and some small outages. This will free up a bunch of CPU, RAM and storage hardware all over the cluster which gives me a lot more room for more fun systems. Notably, it will free up an entire N100 mini PC and some SSDs to use as a ZFS-enabled NAS.</p>

<h2 id="setting-up-lvm-localpv">Setting up LVM localpv</h2>

<p>In the Kubernetes cluster where I wanted to use the storage, I just needed to <a href="https://github.com/openebs/lvm-localpv/blob/develop/docs/quickstart.md#installation">install the CSI driver with helm</a>, eg:</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code>helm repo add openebs https://openebs.github.io/openebs
helm repo update
helm <span class="nb">install </span>openebs <span class="nt">--namespace</span> openebs openebs/openebs <span class="nt">--create-namespace</span>
</code></pre></div></div>

<p>Ironically, this helm chart installs a whole bunch of other storage services, including another replicated storage engine: <a href="https://github.com/openebs/mayastor">Mayastor</a>. I am not planning to use this. If you like, you can choose not to install these other services - the <a href="https://openebs.io/docs/quickstart-guide/installation">OpenEBS installation instructions</a> tell you how to do this.</p>

<p>After this I needed a storage class, which was <code class="language-plaintext highlighter-rouge">kubectl apply</code>‘ed to the cluster:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">apiVersion</span><span class="pi">:</span> <span class="s">storage.k8s.io/v1</span>
<span class="na">kind</span><span class="pi">:</span> <span class="s">StorageClass</span>
<span class="na">metadata</span><span class="pi">:</span>
  <span class="na">name</span><span class="pi">:</span> <span class="s">openebs-lvmpv</span>
<span class="na">parameters</span><span class="pi">:</span>
  <span class="na">storage</span><span class="pi">:</span> <span class="s2">"</span><span class="s">lvm"</span>
  <span class="na">volgroup</span><span class="pi">:</span> <span class="s2">"</span><span class="s">openebs-lvmpv"</span> <span class="c1"># must match the VG name you created</span>
  <span class="na">fsType</span><span class="pi">:</span> <span class="s">ext4</span>
<span class="na">provisioner</span><span class="pi">:</span> <span class="s">local.csi.openebs.io</span>
<span class="na">allowVolumeExpansion</span><span class="pi">:</span> <span class="kc">true</span>   <span class="c1"># optional but recommended</span>
<span class="c1"># don't create the LV until the container is allocated (so it is made in the right VM)</span>
<span class="na">volumeBindingMode</span><span class="pi">:</span> <span class="s">WaitForFirstConsumer</span>
<span class="c1"># after releasing a PVC, keep the LV. To free up storage for reallocation it needs to </span>
<span class="c1"># be manually deleted on the host with `lvremove`.</span>
<span class="na">reclaimPolicy</span><span class="pi">:</span> <span class="s">Retain</span>
</code></pre></div></div>

<h2 id="osd-draining-and-removal">OSD Draining and removal</h2>

<p>Actually allocating a <code class="language-plaintext highlighter-rouge">PV</code> to this <code class="language-plaintext highlighter-rouge">StorageClass</code> means creating a <code class="language-plaintext highlighter-rouge">VG</code> called <code class="language-plaintext highlighter-rouge">openebs-lvmpv</code> on nodes that are allowed to use it. In my cluster all storage is fully allocated. Draining and removing a single <code class="language-plaintext highlighter-rouge">OSD</code> will give me enough space to migrate everything (eg a spare 4TB drive) - a larger cluster would mean more planning and more work.</p>

<p>This is “The Safe-ish Way”(TM). Using “The Dangerous Way” (delete a VM and format its OSD) <em>should</em> be a perfectly valid way of reclaiming the space also, but would put the cluster into a degraded mode straight away and fire off a ton of recovery network activity for <em>hours</em>.</p>

<p>Of course, I skipped a few steps to do with OSD node allocation, OSD pod deletion and operator re-enabling since this cluster is getting deleted. These are the <em>rough</em> steps I followed, and will result in a half-baked clean up and semi-broken cluster. Fine in my case since I’m deleting the whole thing once I’m finished, so take these notes as inspiration rather than instruction:</p>

<p>Before starting, make sure there is enough free space and that the cluster is healthy with the UI or toolbox pod, eg:</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code>ceph <span class="nb">df
</span>ceph osd <span class="nb">df
</span>ceph osd pool <span class="nb">ls </span>detail   <span class="c"># check size and failure domain</span>

<span class="c"># make sure cluster is healthy before proceeding</span>
ceph status
</code></pre></div></div>

<p>Then do the operation itself:</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c"># 1. Stop rook from trying to reclaim devices and nodes, set </span>
<span class="c">#       useAllDevices: false</span>
<span class="c">#       useAllNodes: false</span>

kubectl <span class="nt">-n</span> rook-ceph edit cephcluster rook-ceph

<span class="c"># 2. Stop the operator so it doesn't fight us</span>
kubectl <span class="nt">-n</span> rook-ceph scale deploy rook-ceph-operator <span class="nt">--replicas</span><span class="o">=</span>0

<span class="c"># 3. In the toolbox: mark it out (the OSD stays up and drains gracefully)</span>
ceph osd out osd.&lt;ID&gt;

<span class="c"># 4. I had to wait about a day for all PGs to be active+clean</span>
ceph osd safe-to-destroy osd.&lt;ID&gt;    <span class="c"># confirm it's safe to delete now</span>

<span class="c"># 5. Stop the OSD pod</span>
kubectl <span class="nt">-n</span> rook-ceph scale deploy rook-ceph-osd-&lt;ID&gt; <span class="nt">--replicas</span><span class="o">=</span>0

<span class="c"># 6. In the toolbox: remove it from CRUSH, auth, and the osdmap</span>
ceph osd purge &lt;ID&gt;  <span class="c"># only works if safe to delete</span>
ceph osd crush <span class="nb">rm</span> &lt;<span class="nb">hostname</span><span class="o">&gt;</span>      
</code></pre></div></div>

<h2 id="kubernetes-node-shutdown">Kubernetes node shutdown</h2>

<p>With the data drained from the OSD, I had no use for the Kubernetes node it was attached to any more. I deleted the node from Kubernetes with <code class="language-plaintext highlighter-rouge">kubectl delete node ...</code>, then powered off the VM and <code class="language-plaintext highlighter-rouge">virsh undefine</code>‘d it.</p>

<p>This took out a <a href="https://docs.ceph.com/en/latest/man/8/ceph-mon/"><code class="language-plaintext highlighter-rouge">mon</code></a> for me, and because the operator was scaled to zero, this did not get fixed. Since I had plenty of redundancy it wasn’t a problem but this is a good gotcha to look for in your own migrations.</p>

<p>The old OSD was a pass-through disk so was now sitting unused.</p>

<h2 id="getting-the-disk-to-the-kubernetes-node">Getting the disk to the Kubernetes node</h2>

<p>To actually get the freed up disk available at the point of use in the <code class="language-plaintext highlighter-rouge">crypto</code> node, I formatted it as regular ext4 <em>on the hypervisor</em>, mounted it to <code class="language-plaintext highlighter-rouge">/data/nvme</code> and then created a <code class="language-plaintext highlighter-rouge">.qcow2</code> file under <code class="language-plaintext highlighter-rouge">/data/nvme</code> which was mapped as storage in the <code class="language-plaintext highlighter-rouge">crypto</code> Kubernetes VM. There are some pros and cons to using qcow2 files but on balance, I think it’s fine for what I want to do:</p>
<ul>
  <li>One physical device can only be shared with one VM</li>
  <li>In the Rook/Ceph world, it makes sense to just pass the whole drive through to the VM</li>
  <li><a href="https://en.wikipedia.org/wiki/Qcow">qcow2</a> add some operational overhead and additional management but I’m not planning to change too many things, and I already wrote Ansible scripts to create and map the files to libvirt XML</li>
  <li>I can create additional <code class="language-plaintext highlighter-rouge">.qcow2</code> files and share with different VMs for different Kubernetes nodes if I want to, eg for my <code class="language-plaintext highlighter-rouge">apps</code> cluster</li>
  <li>Beware of overcommitting - qcow2 files are sparse by default, so nothing will stop you allocating a 10TB file on a 500GB disk</li>
</ul>

<p>It’s possible to do some <a href="https://computingforgeeks.com/how-to-configure-a-logical-volume-storage-pool-in-kvm/">cool things with LVM storage pools and KVM/Libvirt</a> to make allocation a slicker process. I decided against this in my lab since I’m already using <code class="language-plaintext highlighter-rouge">.qcow2</code> files for the OS images and I didn’t want two different ways of managing disks in the lab.</p>

<h2 id="lvm-vg-creation">LVM VG creation</h2>

<p>After rebooting the VM (Ansible script requirement), I had a free disk to use for whatever I wanted so I just did what I normally do with a new disk:</p>

<ol>
  <li><code class="language-plaintext highlighter-rouge">gparted /dev/somedisk</code> - Create <code class="language-plaintext highlighter-rouge">GPT</code> partition table, allocate LVM to the whole drive</li>
  <li><code class="language-plaintext highlighter-rouge">pvcreate /dev/somedisk1</code> - the partition you created</li>
  <li><code class="language-plaintext highlighter-rouge">vgcreate openebs-lvmpv /dev/somedisk1</code> - must match above</li>
</ol>

<p>No need to create any <code class="language-plaintext highlighter-rouge">LV</code>s - that’s what the localpv driver does for us.</p>

<h2 id="copy-out-of-existing-pods">Copy out of existing pods</h2>

<p>Copying out the data from Rook/Ceph to LVM was straightforward, if a little slow:</p>

<h3 id="create-a-pvc">Create a <code class="language-plaintext highlighter-rouge">PVC</code></h3>

<p>First create a <code class="language-plaintext highlighter-rouge">PVC</code>, nothing gets allocated yet:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">apiVersion</span><span class="pi">:</span> <span class="s">v1</span>
<span class="na">kind</span><span class="pi">:</span> <span class="s">PersistentVolumeClaim</span>
<span class="na">metadata</span><span class="pi">:</span>
  <span class="na">name</span><span class="pi">:</span> <span class="s">lvm-meowcoin-pvc</span>
  <span class="na">namespace</span><span class="pi">:</span> <span class="s">crypto</span>
<span class="na">spec</span><span class="pi">:</span>
  <span class="na">accessModes</span><span class="pi">:</span>
    <span class="pi">-</span> <span class="s">ReadWriteOnce</span>
  <span class="na">storageClassName</span><span class="pi">:</span> <span class="s">openebs-lvmpv</span>
  <span class="na">resources</span><span class="pi">:</span>
    <span class="na">requests</span><span class="pi">:</span>
      <span class="na">storage</span><span class="pi">:</span> <span class="s">10Gi</span>
</code></pre></div></div>

<h3 id="assign-to-a-pod-with-a-selector">Assign to a pod, with a selector</h3>

<p>Now we want to start a pod with both the Rook/Ceph and LVM storage mounted at the same time. A dedicated pod could be used for this, but since I need to alter the deployment anyway, I just did it all in one place.</p>

<p>Note that <code class="language-plaintext highlighter-rouge">Recreate</code> strategy is used to ensure pods are shut down cleanly because the storage <code class="language-plaintext highlighter-rouge">PVC</code> can only be mounted to one <em>node</em> at a time since it’s marked <code class="language-plaintext highlighter-rouge">ReadWriteOnce</code>. This doesn’t prevent two pods <em>on the same node</em> from doing so though! Eg during a rolling restart. There are a few ways to ensure only one pod at a time has a PVC mounted but this is what works for me and it was the answer to multiple blockchain corruption incidents over the years:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">apiVersion</span><span class="pi">:</span> <span class="s">apps/v1</span>
<span class="na">kind</span><span class="pi">:</span> <span class="s">Deployment</span>
<span class="na">metadata</span><span class="pi">:</span>
  <span class="na">namespace</span><span class="pi">:</span> <span class="s">crypto</span>
  <span class="na">name</span><span class="pi">:</span> <span class="s">meowcoin</span>
<span class="na">spec</span><span class="pi">:</span>
  <span class="na">replicas</span><span class="pi">:</span> <span class="m">1</span>
  <span class="na">strategy</span><span class="pi">:</span>
    <span class="na">type</span><span class="pi">:</span> <span class="s">Recreate</span>
  <span class="na">selector</span><span class="pi">:</span>
    <span class="na">matchLabels</span><span class="pi">:</span>
      <span class="na">app</span><span class="pi">:</span> <span class="s">meowcoin</span>
  <span class="na">template</span><span class="pi">:</span>
    <span class="na">metadata</span><span class="pi">:</span>
      <span class="na">name</span><span class="pi">:</span> <span class="s">meowcoin</span>
      <span class="na">labels</span><span class="pi">:</span>
        <span class="na">app</span><span class="pi">:</span> <span class="s">meowcoin</span>
    <span class="na">spec</span><span class="pi">:</span>
      <span class="na">hostname</span><span class="pi">:</span> <span class="s">meowcoin</span>
      <span class="na">nodeSelector</span><span class="pi">:</span>
        <span class="c1"># make sure we run only on this one server:</span>
        <span class="na">kubernetes.io/hostname</span><span class="pi">:</span> <span class="s">kps-crypto-1</span> 
      <span class="na">containers</span><span class="pi">:</span>
      <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">meowcoind</span>
        <span class="na">image</span><span class="pi">:</span> <span class="s">quay.io/declarativesystems/cryptodaemons_meowcoin:30.2.7</span>

        <span class="c1"># Make a pod that just runs sleep so we can `exec` into it...</span>
        <span class="na">command</span><span class="pi">:</span> <span class="pi">[</span><span class="nv">/bin/sleep</span><span class="pi">]</span>
        <span class="na">args</span><span class="pi">:</span> <span class="pi">[</span><span class="nv">infinity</span><span class="pi">]</span>

        <span class="c1"># ...and disable the normal pod actions...</span>
        <span class="c1"># args:</span>
        <span class="c1"># - "-server"</span>
        <span class="c1"># - "-printtoconsole"</span>
        <span class="na">volumeMounts</span><span class="pi">:</span>
        <span class="pi">-</span> <span class="na">mountPath</span><span class="pi">:</span> <span class="s">/root/.meowcoin</span>
          <span class="na">name</span><span class="pi">:</span> <span class="s">meowcoin</span>
        <span class="pi">-</span> <span class="na">mountPath</span><span class="pi">:</span> <span class="s">/new</span>
          <span class="na">name</span><span class="pi">:</span> <span class="s">meowcoin-new</span>
        <span class="na">resources</span><span class="pi">:</span>
          <span class="na">limits</span><span class="pi">:</span>
            <span class="na">memory</span><span class="pi">:</span> <span class="s2">"</span><span class="s">2Gi"</span>
            <span class="na">cpu</span><span class="pi">:</span> <span class="m">1</span>

      <span class="na">restartPolicy</span><span class="pi">:</span> <span class="s">Always</span>
      <span class="na">volumes</span><span class="pi">:</span>
      <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">meowcoin</span>
        <span class="na">persistentVolumeClaim</span><span class="pi">:</span>
          <span class="na">claimName</span><span class="pi">:</span> <span class="s">rook-ceph-meowcoin-pvc</span>
      <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">meowcoin-new</span>
        <span class="na">persistentVolumeClaim</span><span class="pi">:</span>
          <span class="na">claimName</span><span class="pi">:</span> <span class="s">lvm-meowcoin-pvc</span>     
</code></pre></div></div>

<p>Applying this takes down the <code class="language-plaintext highlighter-rouge">meowcoin</code> server and brings up a pod we can use to copy the data between filesystems. After checking the allocations are correct with <code class="language-plaintext highlighter-rouge">df -h</code>, the data can easily be copied, eg:</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nb">cp</span> <span class="nt">-a</span> /root/.meowcoin/. /new/
</code></pre></div></div>

<p>After the command completes, I checked with <code class="language-plaintext highlighter-rouge">df -h</code> that about the same amount of storage was being used on the LVM mount as the Rook/Ceph one, which is good enough for me.</p>

<p>A better check would have been <code class="language-plaintext highlighter-rouge">du -s</code> on both directories or even running <code class="language-plaintext highlighter-rouge">rsync</code> might be a useful secondary verification. Not a big deal in this case since the crypto server would just sync any missing blockchain data.</p>

<h2 id="return-to-service">Return to service</h2>

<p>Once this finishes, we reconfigure the deployment for production use again:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">apiVersion</span><span class="pi">:</span> <span class="s">apps/v1</span>
<span class="na">kind</span><span class="pi">:</span> <span class="s">Deployment</span>
<span class="na">metadata</span><span class="pi">:</span>
  <span class="na">namespace</span><span class="pi">:</span> <span class="s">crypto</span>
  <span class="na">name</span><span class="pi">:</span> <span class="s">meowcoin</span>
<span class="na">spec</span><span class="pi">:</span>
  <span class="na">replicas</span><span class="pi">:</span> <span class="m">1</span>
  <span class="na">strategy</span><span class="pi">:</span>
    <span class="na">type</span><span class="pi">:</span> <span class="s">Recreate</span>
  <span class="na">selector</span><span class="pi">:</span>
    <span class="na">matchLabels</span><span class="pi">:</span>
      <span class="na">app</span><span class="pi">:</span> <span class="s">meowcoin</span>
  <span class="na">template</span><span class="pi">:</span>
    <span class="na">metadata</span><span class="pi">:</span>
      <span class="na">name</span><span class="pi">:</span> <span class="s">meowcoin</span>
      <span class="na">labels</span><span class="pi">:</span>
        <span class="na">app</span><span class="pi">:</span> <span class="s">meowcoin</span>
    <span class="na">spec</span><span class="pi">:</span>
      <span class="na">hostname</span><span class="pi">:</span> <span class="s">meowcoin</span>
      <span class="na">nodeSelector</span><span class="pi">:</span>
        <span class="c1"># make sure we run only on this one server:</span>
        <span class="na">kubernetes.io/hostname</span><span class="pi">:</span> <span class="s">kps-crypto-1</span> 
      <span class="na">containers</span><span class="pi">:</span>
      <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">meowcoind</span>
        <span class="na">image</span><span class="pi">:</span> <span class="s">quay.io/declarativesystems/cryptodaemons_meowcoin:30.2.7</span>

        <span class="c1"># Keep for emergencies...</span>
        <span class="c1"># command: [/bin/sleep]</span>
        <span class="c1"># args: [infinity]</span>

        <span class="c1"># ...and restore the normal pod actions...</span>
        <span class="na">args</span><span class="pi">:</span>
        <span class="pi">-</span> <span class="s2">"</span><span class="s">-server"</span>
        <span class="pi">-</span> <span class="s2">"</span><span class="s">-printtoconsole"</span>
        <span class="na">volumeMounts</span><span class="pi">:</span>
        <span class="pi">-</span> <span class="na">mountPath</span><span class="pi">:</span> <span class="s">/root/.meowcoin</span>
          <span class="na">name</span><span class="pi">:</span> <span class="s">meowcoin</span>
        <span class="na">resources</span><span class="pi">:</span>
          <span class="na">limits</span><span class="pi">:</span>
            <span class="na">memory</span><span class="pi">:</span> <span class="s2">"</span><span class="s">2Gi"</span>
            <span class="na">cpu</span><span class="pi">:</span> <span class="m">1</span>

      <span class="na">restartPolicy</span><span class="pi">:</span> <span class="s">Always</span>
      <span class="na">volumes</span><span class="pi">:</span>
      <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">meowcoin</span>
        <span class="na">persistentVolumeClaim</span><span class="pi">:</span>
          <span class="na">claimName</span><span class="pi">:</span> <span class="s">lvm-meowcoin-pvc</span>     
</code></pre></div></div>

<p>A few seconds later, the pod was up and running with all required data.</p>

<h2 id="clean-up">Clean up</h2>

<p>Once the new pod is up and running the Rook/Ceph <code class="language-plaintext highlighter-rouge">PVC</code> can be deleted, which should free up its storage unless you changed the default <code class="language-plaintext highlighter-rouge">reclaimPolicy</code>.</p>

<p>After repeating the process above for all <code class="language-plaintext highlighter-rouge">PVC</code>s in the Rook/Ceph cluster and double-checking my work, I was left with a Rook/Ceph cluster that was still happily running OSDs and other pods. If I was keeping the cluster then additional clean up steps would be needed to restore normal operations. If you need to do this, I suggest you <a href="https://rook.io/docs/rook/latest-release/Getting-Started/intro/">read the instructions carefully</a>.</p>

<p>In my case, this is the end of this Rook/Ceph cluster. Since it runs entirely within KVM via libvirt, I didn’t bother to properly clean up anything, I just <code class="language-plaintext highlighter-rouge">virsh destroy</code>ed and <code class="language-plaintext highlighter-rouge">virsh undefine</code>ed until the entire Kubernetes cluster was deleted.</p>

<p>At this point, the pass-through OSD disks could be repartitioned with <code class="language-plaintext highlighter-rouge">cfdisk</code>.</p>

<p>The final step of clean up was to remove the Rook/Ceph deployment from the <em>consumer</em> cluster, by uninstalling the helm chart and deleting the namespace.</p>

<h2 id="tips-and-tricks">Tips and tricks</h2>

<h3 id="use-screen-if-available">Use screen if available</h3>

<p>In case your session gets interrupted, you can use <code class="language-plaintext highlighter-rouge">tmux</code> or <code class="language-plaintext highlighter-rouge">screen</code> inside the pod if it’s available, so your command doesn’t stop if your <code class="language-plaintext highlighter-rouge">kubectl exec</code> disconnects for some reason.</p>

<p>If it’s missing and you’re lucky, you might be able to <code class="language-plaintext highlighter-rouge">apt install</code> it.</p>

<h3 id="local-storage">local-storage</h3>

<p>Don’t forget you can still use <a href="https://docs.k3s.io/add-ons/storage#setting-up-the-local-storage-provider">K3s built-in <code class="language-plaintext highlighter-rouge">local-storage</code></a> as an alternative path to copy out data from Rook/Ceph if you’re having trouble finding space elsewhere. Similar technique to above.</p>

<h3 id="grow-an-lv">Grow an LV</h3>

<p>If you need more space, you can just <em>increase</em> the value of the <code class="language-plaintext highlighter-rouge">storage</code> field and apply your <code class="language-plaintext highlighter-rouge">yaml</code>. A couple of minutes later, the additional space was available in the pod with no restart needed. Eg:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">apiVersion</span><span class="pi">:</span> <span class="s">v1</span>
<span class="na">kind</span><span class="pi">:</span> <span class="s">PersistentVolumeClaim</span>
<span class="na">metadata</span><span class="pi">:</span>
  <span class="na">name</span><span class="pi">:</span> <span class="s">lvm-meowcoin-pvc</span>
  <span class="na">namespace</span><span class="pi">:</span> <span class="s">crypto</span>
<span class="na">spec</span><span class="pi">:</span>
  <span class="na">accessModes</span><span class="pi">:</span>
    <span class="pi">-</span> <span class="s">ReadWriteOnce</span>
  <span class="na">storageClassName</span><span class="pi">:</span> <span class="s">openebs-lvmpv</span>
  <span class="na">resources</span><span class="pi">:</span>
    <span class="na">requests</span><span class="pi">:</span>
      <span class="na">storage</span><span class="pi">:</span> <span class="s">50Gi</span> <span class="c1"># &lt;~~~ edit here</span>
</code></pre></div></div>

<h2 id="what-did-i-lose">What did I lose?</h2>

<p>The switch has some drawbacks, that I willingly signed up for:</p>
<ul>
  <li>Storage is now explicitly pinned to nodes, it does not “float” around the cluster anymore</li>
  <li>Pods are manually pinned to Kubernetes nodes:
    <ul>
      <li>Pods are linked to a named <code class="language-plaintext highlighter-rouge">PVC</code>, so moving a workload means pinning the <code class="language-plaintext highlighter-rouge">deployment</code> to another Kubernetes node <em>and</em> creating a new <code class="language-plaintext highlighter-rouge">PVC</code> with a new name, so Kubernetes can create it in the right place</li>
      <li>If a pod restarts with a fresh <code class="language-plaintext highlighter-rouge">PVC</code> it needs to download its entire blockchain from the peer-to-peer network again. This can take days unless I build a NAS and write a backup and restore procedure to get up and running quicker</li>
      <li>The typical worst case would be a brief outage of minutes/hours while a mini PC is rebooted or has maintenance done on it</li>
      <li>Additional manual steps to restore operation make the advantage of Kubernetes less compelling in this case but do not eliminate it altogether. It’s still the best way to manage containerized apps for my workload</li>
    </ul>
  </li>
  <li>No more replicated storage</li>
  <li>No UI</li>
  <li>No S3 compatible storage</li>
  <li>No “storage as a service” for other Kubernetes clusters</li>
</ul>

<h2 id="what-did-i-gain">What did I gain?</h2>

<p>Crypto nodes don’t really benefit from replicated storage the way I had it set up:</p>
<ul>
  <li>The data is already replicated over the peer-to-peer network</li>
  <li>The “floating” storage was fun to test out and speeds up crypto node restarts, but restarts still take several minutes, during which, the node cannot be used.</li>
  <li>If some kind of HA crypto node was actually needed (eg for an exchange), then the way to do this is with multiple, independent nodes - with their own independent storage. I don’t have the need or the hardware for this</li>
  <li>Mitigation for slow node rebuilding (hours/days) if a disk fails is to periodically snapshot the blockchain data to the NAS I’m planning on building, or just replace the drive and suck up the delay in the interim</li>
</ul>

<p>I knew this walking into my distributed storage adventure of course - running a crypto server is a low-stress, low-effort way to get some constantly updating data to play with on your storage cluster. If you want to start over, you can do so guilt- and worry-free.</p>

<p>In terms of extra hardware, I gain:</p>
<ul>
  <li>Entire 16GB N100 mini PC</li>
  <li>Valuable SSDs and NVMes (at least 2x 4TB drives)</li>
  <li>CPU and RAM used by 5 big VMs on 5 PCs</li>
  <li>Not storing 3 copies of all data means a 66% reduction in lab storage needed</li>
  <li>I’m wondering if this will even bring down the power bill (or room temperature)</li>
</ul>

<p>And in terms of admin:</p>
<ul>
  <li>5 <em>big</em> VMs no longer need monitoring, etc</li>
  <li>2 VLANs can be retired</li>
  <li>Network traffic rules can be simplified</li>
  <li>Less traffic on the LAN in general - important on a 1GbE network</li>
  <li>No more scary Rook/Ceph upgrades</li>
</ul>

<h2 id="conclusion">Conclusion</h2>

<p>I hope reading this you don’t think I’m picking faults with Rook/Ceph - I’m not, it’s excellent. I’ve learned a lot using it, but the more useful workloads I planned to use with it failed to materialize and for my crypto homelab it’s like using a nuclear weapon to swat a fly.</p>

<p>Using Rook/Ceph daily also confirmed to me that if I was going to use this for something important or a customer, a single 1GbE network cluster is not going to cut it. Production needs mean faster networking, multiple clusters and probably a support contract.</p>

<p>Onward!</p>]]></content><author><name>Geoff Williams</name><email>geoff@declarativesystems.com</email></author><category term="rook" /><category term="ceph" /><category term="homelab" /><category term="nas" /><category term="lvm" /><category term="kubernetes" /><category term="storage" /><category term="devops" /><summary type="html"><![CDATA[Swapping a nuclear weapon for a flyswatter - moving my homelab off Rook/Ceph to plain LVM.]]></summary></entry><entry><title type="html">Homelab - Agentic AI vs routine maintenance + Rook/Ceph upgrade</title><link href="/2026/09/10/homelab-agentic-vs-maintenance.html" rel="alternate" type="text/html" title="Homelab - Agentic AI vs routine maintenance + Rook/Ceph upgrade" /><published>2026-09-10T00:00:00+00:00</published><updated>2026-09-10T00:00:00+00:00</updated><id>/2026/09/10/homelab-agentic-vs-maintenance</id><content type="html" xml:base="/2026/09/10/homelab-agentic-vs-maintenance.html"><![CDATA[<p>Every now and then, one of the homelab VMs crashes. An ideal problem for agentic AI with a human-in-the-loop?</p>

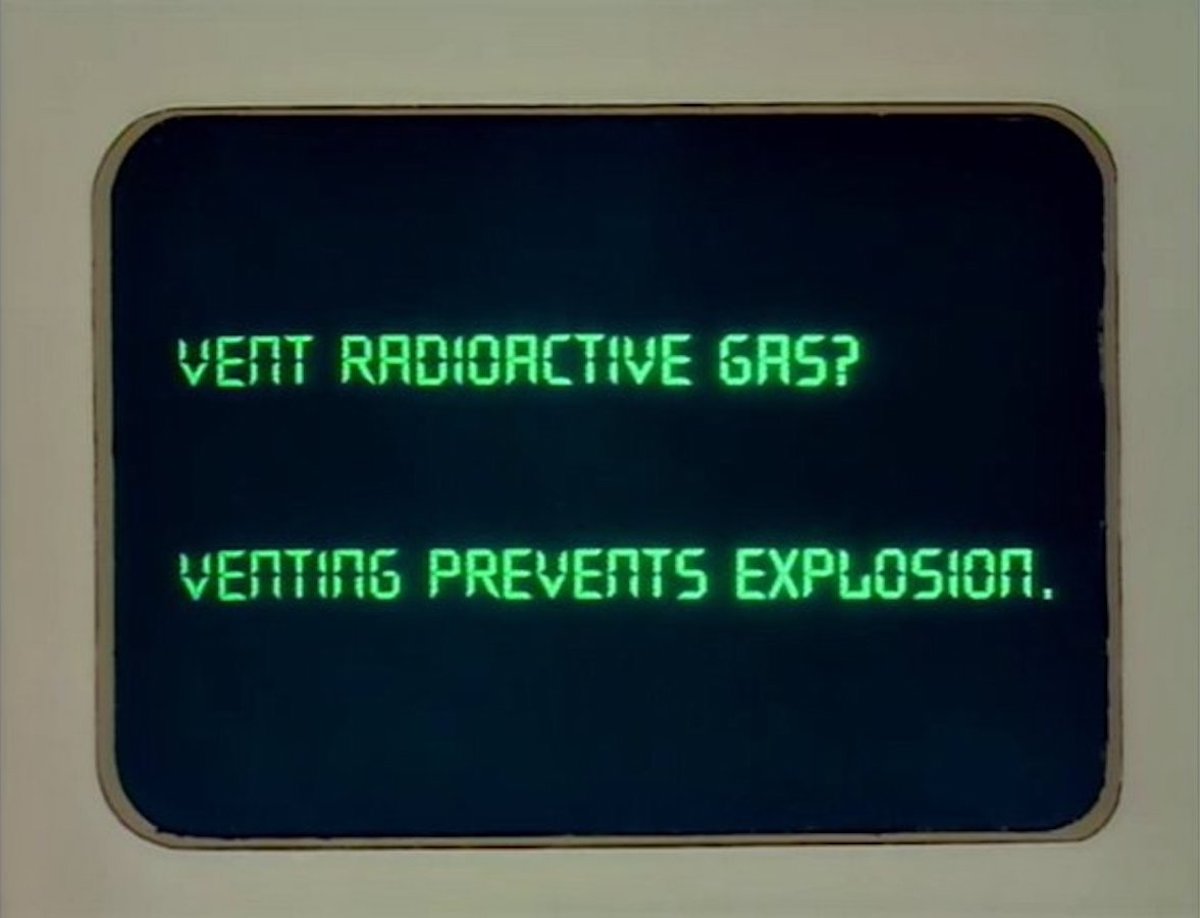
<p>I did some research already on why this happens and it’s due to <code class="language-plaintext highlighter-rouge">OOMKILL</code> at the hypervisor level. Rebooting fixes it - until next time. A finite choice human-gated solution might render a screen that looks something like this one, from <a href="https://en.wikipedia.org/wiki/King-Size_Homer">“King-Size Homer”</a>:</p>

<p><img src="/assets/img/simpsons_venting_prevents_explosion.jpg" alt="vent radioactive gas" /></p>

<p>Which could then be approved by the operator (or not):</p>

<p><img src="/assets/img/simpsons_no.gif" alt="homer says no" /></p>

<p>Building this would have been a complete waste of time, effort and tokens. The problems and solutions are known, so let’s just fix this once and for all, and save our <em>agentic loop</em> for a real problem.</p>

<h2 id="what-keeps-breaking">What keeps breaking?</h2>

<p>Looking through the kernel errors, I could see a VM being <code class="language-plaintext highlighter-rouge">OOMKILL</code>‘ed about once every couple of months. The reason for this is very simple: The hypervisor is overcommitted and has swap disabled. This was originally done for performance reasons but it means a temporary increase in memory usage will result in the kernel reclaiming memory the only way it can - by killing processes.</p>

<p>The lab runs mostly on mini PCs with limited memory - 16-32GB. The 32GB boxes lose 4GB to onboard graphics and are <em>always</em> the PCs with problems since most of the work is allocated to them.</p>

<h2 id="todoexe">TODO.exe</h2>

<p>This little cluster has been running for a couple of years without much maintenance being done, so it’s due for some updates. I came up with a five-step plan to fix the memory issues once and for all, as well as some routine upgrades:</p>

<ol>
  <li>Enable swap at the host (hypervisor) level</li>
  <li>Upgrade Rook/Ceph</li>
  <li>Upgrade Kubernetes (K3s)</li>
  <li>Reduce memory allocations for VMs to fix excessive overcommit</li>
  <li>Use <a href="https://en.wikipedia.org/wiki/Cgroups">cgroups</a> to reserve memory for the host (hypervisor)</li>
</ol>

<h2 id="enabling-swap">Enabling swap</h2>

<p>This was the most straight-forward fix since the hypervisors are managed with ansible. I added some code to my SOE, activated for <em>physical servers only</em> (hypervisors, not Kubernetes nodes) and moved on quickly:</p>

<p>Vars:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">swapfile_path</span><span class="pi">:</span> <span class="s2">"</span><span class="s">/swapfile"</span>
<span class="na">swapfile_size</span><span class="pi">:</span> <span class="s">8G</span>

<span class="c1"># prefer dropping page cache over swapping out guest RAM under reclaim.</span>
<span class="c1"># swap here is an emergency valve to buy the kernel time, not memory</span>
<span class="c1"># we intend to run in</span>
<span class="na">swappiness_value</span><span class="pi">:</span> <span class="m">10</span>
</code></pre></div></div>

<p>Tasks:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code>
<span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">Create swapfile</span>
  <span class="na">community.general.filesize</span><span class="pi">:</span>
    <span class="na">path</span><span class="pi">:</span> <span class="s2">"</span><span class="s">{{</span><span class="nv"> </span><span class="s">swapfile_path</span><span class="nv"> </span><span class="s">}}"</span>
    <span class="na">size</span><span class="pi">:</span> <span class="s2">"</span><span class="s">{{</span><span class="nv"> </span><span class="s">swapfile_size</span><span class="nv"> </span><span class="s">}}"</span>
    
<span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">Set swapfile permissions</span>
  <span class="na">ansible.builtin.file</span><span class="pi">:</span>
    <span class="na">path</span><span class="pi">:</span> <span class="s2">"</span><span class="s">{{</span><span class="nv"> </span><span class="s">swapfile_path</span><span class="nv"> </span><span class="s">}}"</span>
    <span class="na">owner</span><span class="pi">:</span> <span class="s">root</span>
    <span class="na">group</span><span class="pi">:</span> <span class="s">root</span>
    <span class="na">mode</span><span class="pi">:</span> <span class="s1">'</span><span class="s">0600'</span>

<span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">Check whether swapfile is already active</span>
  <span class="na">ansible.builtin.command</span><span class="pi">:</span>
    <span class="na">cmd</span><span class="pi">:</span> <span class="s">swapon --show=NAME --noheadings</span>
  <span class="na">register</span><span class="pi">:</span> <span class="s">swapfile_active</span>
  <span class="na">changed_when</span><span class="pi">:</span> <span class="kc">false</span>

<span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">Format swapfile</span>
  <span class="na">ansible.builtin.command</span><span class="pi">:</span>
    <span class="na">cmd</span><span class="pi">:</span> <span class="s2">"</span><span class="s">mkswap</span><span class="nv"> </span><span class="s">{{</span><span class="nv"> </span><span class="s">swapfile_path</span><span class="nv"> </span><span class="s">}}"</span>
  <span class="na">when</span><span class="pi">:</span> <span class="s">swapfile_path not in swapfile_active.stdout_lines</span>
  
<span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">Enable swapfile</span>
  <span class="na">ansible.builtin.command</span><span class="pi">:</span>
    <span class="na">cmd</span><span class="pi">:</span> <span class="s2">"</span><span class="s">swapon</span><span class="nv"> </span><span class="s">{{</span><span class="nv"> </span><span class="s">swapfile_path</span><span class="nv"> </span><span class="s">}}"</span>
  <span class="na">when</span><span class="pi">:</span> <span class="s">swapfile_path not in swapfile_active.stdout_lines</span>

<span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">Persist swapfile</span>
  <span class="na">ansible.posix.mount</span><span class="pi">:</span>
    <span class="na">path</span><span class="pi">:</span> <span class="s">none</span>
    <span class="na">src</span><span class="pi">:</span> <span class="s2">"</span><span class="s">{{</span><span class="nv"> </span><span class="s">swapfile_path</span><span class="nv"> </span><span class="s">}}"</span>
    <span class="na">fstype</span><span class="pi">:</span> <span class="s">swap</span>
    <span class="na">opts</span><span class="pi">:</span> <span class="s">sw</span>
    <span class="na">state</span><span class="pi">:</span> <span class="s">present</span>

<span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">Configure swappiness</span>
  <span class="na">ansible.posix.sysctl</span><span class="pi">:</span>
    <span class="na">name</span><span class="pi">:</span> <span class="s">vm.swappiness</span>
    <span class="na">value</span><span class="pi">:</span> <span class="s2">"</span><span class="s">{{</span><span class="nv"> </span><span class="s">swappiness_value</span><span class="nv"> </span><span class="s">}}"</span>
    <span class="na">state</span><span class="pi">:</span> <span class="s">present</span>
    <span class="na">reload</span><span class="pi">:</span> <span class="kc">true</span>

</code></pre></div></div>

<h2 id="upgrading-rookceph">Upgrading Rook/Ceph</h2>

<p><a href="https://rook.io/">Rook/Ceph</a> is used in the homelab as replicated, Cloud-Native Storage for Kubernetes.</p>

<p>Upgrading Rook/Ceph is a serious undertaking. It’s actually not dissimilar in scale to upgrading <a href="https://www.confluent.io/product/confluent-platform/">Confluent Platform</a> (my day job), with a lot less hand-holding. Fortunately, there’s no valuable data on my Rook/Ceph cluster since I just use it to host a few crypto nodes.</p>

<p>The notes below <strong>supplement</strong> the docs:</p>

<ul>
  <li>Cluster must be healthy before starting</li>
  <li>Upgrade one minor release at a time, eg 1.16.x to 1.17.x</li>
  <li><a href="https://rook.io/docs/rook/latest-release/Getting-Started/intro/">RTFM!</a></li>
  <li>No really. RTFM. For each minor release you will upgrade through</li>
  <li>Upgrade <code class="language-plaintext highlighter-rouge">rook-ceph</code> first, then <code class="language-plaintext highlighter-rouge">rook-ceph-cluster</code></li>
  <li>You must install/upgrade <code class="language-plaintext highlighter-rouge">ceph-csi-drivers</code> if you want to be able to access PVs (you do)</li>
  <li>Wait for each upgrade step to finish before moving on</li>
</ul>

<p>Helm tips:</p>

<ul>
  <li>Helm charts do most of the work</li>
  <li>Explore available versions:
    <ul>
      <li><code class="language-plaintext highlighter-rouge">helm search repo rook-release/rook-ceph --versions</code></li>
      <li><code class="language-plaintext highlighter-rouge">helm search repo rook-release/rook-ceph-cluster --versions</code></li>
    </ul>
  </li>
  <li>List what’s installed: <code class="language-plaintext highlighter-rouge">helm list -A</code></li>
</ul>

<p>Example (upgrade v1.16.5 to v1.17.9):</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c"># Upgrade the operator</span>
helm upgrade <span class="nt">--version</span> v1.17.9  <span class="nt">--namespace</span> rook-ceph rook-ceph rook-release/rook-ceph

<span class="c"># WAIT for all pods to show correct version</span>
watch <span class="s2">"kubectl -n rook-ceph get deploy </span><span class="se">\</span><span class="s2">
  -o custom-columns=NAME:.metadata.name,ROOK:.metadata.labels.rook-version"</span>

<span class="c"># Install the CSI driver now, (omitted in my lab environment)</span>

<span class="c"># Upgrade the cluster itself, using saved values from the original deploy</span>
helm upgrade <span class="nt">--version</span> v1.17.9  <span class="nt">--namespace</span> rook-ceph rook-ceph-cluster rook-release/rook-ceph-cluster <span class="nt">-f</span> helm_values/rook_cluster_values.yaml

<span class="c"># WAIT - watching the logs</span>
kubectl logs  <span class="nt">-n</span> rook-ceph rook-ceph-operator-5cc9ff9d9b-9zp7k <span class="nt">-f</span>
</code></pre></div></div>

<h3 id="cluster-topology">Cluster topology</h3>
<p>I access the Rook/Ceph storage as an <a href="https://rook.io/docs/rook/latest-release/CRDs/Cluster/external-cluster/external-cluster/">external cluster</a> at the point of use. The Rook/Ceph storage cluster itself lives in a separate, dedicated Kubernetes cluster for ease of management and sharing.</p>

<h3 id="ceph-csi-driver-problems">Ceph-CSI driver problems</h3>
<p>The Kubernetes cluster accessing the Rook/Ceph storage is upgraded with a similar process to the storage cluster. Since this is where I want to use the storage, it’s now mandatory to install the <a href="https://rook.io/docs/rook/latest-release/Helm-Charts/csi-drivers-chart/">Ceph-CSI driver helm chart</a>.</p>

<p>The Ceph-CSI driver actually failed for me and crashed my workloads:</p>
<ul>
  <li>First a couple of pods died with <code class="language-plaintext highlighter-rouge">OOMKILLED</code> (from Kubernetes)</li>
  <li>Thinking the pods must have got stuck for some reason, I rebooted the entire Kubernetes cluster</li>
  <li>At this point, all workloads that attempted to mount storage were marked as <code class="language-plaintext highlighter-rouge">unknown</code> or <code class="language-plaintext highlighter-rouge">ContainerCreating</code> and were blocked from starting or progressing.</li>
</ul>

<p>To troubleshoot this, I did some investigating on the stuck pods and found:</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code>kubectl describe pod &lt;pod-name&gt; <span class="nt">-n</span> &lt;namespace&gt;
...

Type     Reason       Age                   From     Message
  <span class="nt">----</span>     <span class="nt">------</span>       <span class="nt">----</span>                  <span class="nt">----</span>     <span class="nt">-------</span>
  Warning  FailedMount  18m <span class="o">(</span>x119 over 4h4m<span class="o">)</span>  kubelet  MountVolume.MountDevice failed <span class="k">for </span>volume <span class="s2">"pvc-fe440598-6203-4a69-8aad-4032795274e1"</span> : kubernetes.io/csi: attacher.MountDevice failed to create newCsiDriverClient: driver name rook-ceph.rbd.csi.ceph.com not found <span class="k">in </span>the list of registered CSI drivers
  Warning  FailedMount  9s <span class="o">(</span>x14 over 12m<span class="o">)</span>     kubelet  MountVolume.MountDevice failed <span class="k">for </span>volume <span class="s2">"pvc-fe440598-6203-4a69-8aad-4032795274e1"</span> : kubernetes.io/csi: attacher.MountDevice failed to create newCsiDriverClient: driver name rook-ceph.rbd.csi.ceph.com not found <span class="k">in </span>the list of registered CSI drivers
</code></pre></div></div>

<p>Accompanied by no drivers running:</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code>kubectl <span class="nt">-n</span> rook-ceph get ds
NAME                                       DESIRED   CURRENT   READY   UP-TO-DATE   AVAILABLE   NODE SELECTOR   AGE
rook-ceph.cephfs.csi.ceph.com-nodeplugin   3         0         0       0            0           &lt;none&gt;          34h
rook-ceph.rbd.csi.ceph.com-nodeplugin      3         0         0       0            0           &lt;none&gt;          34h
</code></pre></div></div>

<p>Eventually I found the problem - a mismatch between service account names in <code class="language-plaintext highlighter-rouge">ceph-csi-drivers</code> chart vs the deployed cluster:</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code>kubectl describe ds <span class="nt">-n</span> rook-ceph rook-ceph.rbd.csi.ceph.com-nodeplugin

...

Events:
  Type     Reason        Age                   From                  Message
  <span class="nt">----</span>     <span class="nt">------</span>        <span class="nt">----</span>                  <span class="nt">----</span>                  <span class="nt">-------</span>
  Warning  FailedCreate  21m <span class="o">(</span>x37 over 4h9m<span class="o">)</span>   daemonset-controller  Error creating: pods <span class="s2">"rook-ceph.rbd.csi.ceph.com-nodeplugin-"</span> is forbidden: error looking up service account rook-ceph/rbd-nodeplugin-sa: serviceaccount <span class="s2">"rbd-nodeplugin-sa"</span> not found
  Warning  FailedCreate  5m46s <span class="o">(</span>x18 over 16m<span class="o">)</span>  daemonset-controller  Error creating: pods <span class="s2">"rook-ceph.rbd.csi.ceph.com-nodeplugin-"</span> is forbidden: error looking up service account rook-ceph/rbd-nodeplugin-sa: serviceaccount <span class="s2">"rbd-nodeplugin-sa"</span> not found

</code></pre></div></div>

<p>Available service accounts:</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code>kubectl get serviceaccounts <span class="nt">-n</span> rook-ceph 
NAME                                          AGE
ceph-csi                                      34h
default                                       550d
objectstorage-provisioner                     548d
rook-ceph-cephfs-csi-ceph-com-ctrlplugin-sa   90m
rook-ceph-cephfs-csi-ceph-com-nodeplugin-sa   90m
rook-ceph-cmd-reporter                        548d
rook-ceph-default                             548d
rook-ceph-mgr                                 548d
rook-ceph-nvmeof                              34h
rook-ceph-osd                                 548d
rook-ceph-purge-osd                           548d
rook-ceph-rbd-csi-ceph-com-ctrlplugin-sa      90m
rook-ceph-rbd-csi-ceph-com-nodeplugin-sa      90m
rook-ceph-rgw                                 548d
rook-ceph-system                              548d
</code></pre></div></div>

<p>Note that <code class="language-plaintext highlighter-rouge">rbd-nodeplugin-sa</code> has a completely different name on the system: <code class="language-plaintext highlighter-rouge">rook-ceph-rbd-csi-ceph-com-nodeplugin-sa</code>. The same applies to three other service accounts as well.</p>

<p>To fix this I had to add configuration for the service account to the default helm values from the docs by adding <code class="language-plaintext highlighter-rouge">serviceAccountName</code> to fix the four broken accounts. I also had to <code class="language-plaintext highlighter-rouge">helm uninstall</code> the <code class="language-plaintext highlighter-rouge">ceph-csi-drivers</code> chart and reinstall it for this to take effect. It was not enough to just <code class="language-plaintext highlighter-rouge">helm upgrade</code>:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># Rook-compatible default values for the ceph-csi-drivers Helm chart.</span>
<span class="c1">#</span>
<span class="c1"># Use these values when installing or upgrading the ceph-csi-drivers chart</span>
<span class="c1"># alongside the rook-ceph operator chart. The driver names must match the</span>
<span class="c1"># provisioner names used by Rook (e.g. in StorageClasses and VolumeSnapshotClasses).</span>
<span class="c1">#</span>
<span class="c1"># If the Rook operator is installed in a namespace other than rook-ceph, replace</span>
<span class="c1"># "rook-ceph" in the driver names below with your operator namespace.</span>

<span class="na">operatorConfig</span><span class="pi">:</span>
  <span class="na">namespace</span><span class="pi">:</span> <span class="s">rook-ceph</span> <span class="c1"># namespace:operator</span>
  <span class="na">driverSpecDefaults</span><span class="pi">:</span>
    <span class="na">imageSet</span><span class="pi">:</span>
      <span class="na">name</span><span class="pi">:</span> <span class="s">rook-csi-operator-image-set-configmap</span>
    <span class="na">nodePlugin</span><span class="pi">:</span>
      <span class="na">priorityClassName</span><span class="pi">:</span> <span class="s">system-node-critical</span>
    <span class="na">controllerPlugin</span><span class="pi">:</span>
      <span class="na">priorityClassName</span><span class="pi">:</span> <span class="s">system-cluster-critical</span>

<span class="na">drivers</span><span class="pi">:</span>
  <span class="na">rbd</span><span class="pi">:</span>
    <span class="na">enabled</span><span class="pi">:</span> <span class="kc">true</span>
    <span class="na">name</span><span class="pi">:</span> <span class="s">rook-ceph.rbd.csi.ceph.com</span> <span class="c1"># csi-provisioner-name</span>
    <span class="na">nodePlugin</span><span class="pi">:</span>
      <span class="na">serviceAccountName</span><span class="pi">:</span> <span class="s">rook-ceph-rbd-csi-ceph-com-nodeplugin-sa</span>
    <span class="na">controllerPlugin</span><span class="pi">:</span>
      <span class="na">serviceAccountName</span><span class="pi">:</span> <span class="s">rook-ceph-rbd-csi-ceph-com-ctrlplugin-sa</span>    
  <span class="na">cephfs</span><span class="pi">:</span>
    <span class="na">enabled</span><span class="pi">:</span> <span class="kc">true</span>
    <span class="na">name</span><span class="pi">:</span> <span class="s">rook-ceph.cephfs.csi.ceph.com</span> <span class="c1"># csi-provisioner-name</span>
    <span class="na">nodePlugin</span><span class="pi">:</span>
      <span class="na">serviceAccountName</span><span class="pi">:</span> <span class="s">rook-ceph-cephfs-csi-ceph-com-nodeplugin-sa</span>
    <span class="na">controllerPlugin</span><span class="pi">:</span>
      <span class="na">serviceAccountName</span><span class="pi">:</span> <span class="s">rook-ceph-cephfs-csi-ceph-com-ctrlplugin-sa</span>    
  <span class="na">nfs</span><span class="pi">:</span>
    <span class="na">enabled</span><span class="pi">:</span> <span class="kc">false</span>
    <span class="na">name</span><span class="pi">:</span> <span class="s">rook-ceph.nfs.csi.ceph.com</span> <span class="c1"># csi-provisioner-name</span>
  <span class="na">nvmeof</span><span class="pi">:</span>
    <span class="na">enabled</span><span class="pi">:</span> <span class="kc">false</span>
    <span class="na">name</span><span class="pi">:</span> <span class="s">rook-ceph.nvmeof.csi.ceph.com</span> <span class="c1"># csi-provisioner-name</span>
</code></pre></div></div>

<p>No data was lost during the upgrade, although I did have a brief unplanned outage while I worked out the service account fix.</p>

<h2 id="upgrading-kubernetes-k3s">Upgrading Kubernetes (K3s)</h2>

<p>I’m using <a href="https://k3s.io/">K3s</a> as a light-weight Kubernetes distribution and <a href="https://docs.k3s.io/related-projects?_highlight=ansible#k3s-ansible">manage it with k3s-ansible</a>.</p>

<p>Like Rook/Ceph, Kubernetes should also be upgraded through each minor version, in my case there were three minor version updates to apply.</p>

<p>Hats off to the K3s developers, this was incredibly easy having just finished a Rook/Ceph upgrade:</p>

<ol>
  <li>Update the <code class="language-plaintext highlighter-rouge">k3s-ansible</code> codes</li>
  <li>Change <code class="language-plaintext highlighter-rouge">k3s_version</code> to desired version in inventory file</li>
  <li>Run the upgrade playbook (eg <code class="language-plaintext highlighter-rouge">ansible-playbook playbooks/upgrade.yml -i ../inventories/k3s_apps.yml</code>)</li>
  <li>Wait for stability, then rinse and repeat</li>
</ol>

<p>It really was that easy once I figured out I now needed to install the <code class="language-plaintext highlighter-rouge">ansible.utils</code> galaxy module.</p>

<h2 id="reducing-memory-allocations">Reducing memory allocations</h2>

<p>With the upgrades done and systems stable, it was time to redistribute and reduce overall memory usage.</p>

<p>On PCs with 28GB usable RAM, there was an overcommit of approximately 6GB which is far too high. 3GB is pushing it and 0GB of overcommit would be better.</p>

<p>When the cluster was first setup, I remember Rook/Ceph needing a lot more memory but it seems this hasn’t been the case for a long time and much of that memory was sitting idle. Since I control my VMs with libvirt/KVM + ansible, changing memory allocation is a very simple process:</p>

<ol>
  <li>Update <code class="language-plaintext highlighter-rouge">host_vars</code> for hypervisor with new memory amount</li>
  <li>Shut down affected VM(s)</li>
  <li>Run ansible</li>
  <li>VM will be restarted with the updated memory allocation</li>
</ol>

<p>The main reduction was for the Rook/Ceph VMs: from 20GB to 12GB. Some of the future-use clusters were also downsized, from 4GB to 2GB.</p>

<p>An hour or so later the job was done and the VMs worked fine with their new memory allocations.</p>

<h2 id="using-cgroups-to-limit-memory-usage-in-machineslice">Using cgroups to limit memory usage in <code class="language-plaintext highlighter-rouge">machine.slice</code></h2>

<p>Everything we have done so far has been a mitigation for the crashes - this step limits the blast radius of <code class="language-plaintext highlighter-rouge">OOMKILL</code>: When <code class="language-plaintext highlighter-rouge">machine.slice</code> is full, it will kill a VM, <em>not</em> a host process like <code class="language-plaintext highlighter-rouge">sshd</code>.</p>

<p>Linux cgroups are a kernel feature that we can use to restrict the memory available to programs. Limiting the total memory available to VMs in <code class="language-plaintext highlighter-rouge">machine.slice</code> lets us support a modest overcommit more safely without the risk of the hypervisor running out of memory.</p>

<p>We can deploy the change very easily with ansible.</p>

<p>Vars:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># total held back from machine.slice</span>
<span class="na">host_reserve_mb</span><span class="pi">:</span> <span class="m">2048</span>

<span class="c1"># unreclaimable floor, measured</span>
<span class="na">host_min_mb</span><span class="pi">:</span> <span class="m">512</span>

<span class="c1"># best-effort protection</span>
<span class="na">host_low_mb</span><span class="pi">:</span> <span class="m">1024</span>

<span class="c1"># headroom for fwupd/libvirtd spikes</span>
<span class="na">user_low_mb</span><span class="pi">:</span> <span class="m">256</span>

<span class="c1"># unreclaimable floor for ssh/login sessions</span>
<span class="na">user_min_mb</span><span class="pi">:</span> <span class="m">64</span>

<span class="c1"># throttle band: gap between MemoryHigh and MemoryMax</span>
<span class="na">vm_high_headroom_mb</span><span class="pi">:</span> <span class="m">1024</span>
</code></pre></div></div>

<p>Tasks:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code>
<span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">Ensure slice drop-in directories exist</span>
  <span class="na">ansible.builtin.file</span><span class="pi">:</span>
    <span class="na">path</span><span class="pi">:</span> <span class="s2">"</span><span class="s">/etc/systemd/system/{{</span><span class="nv"> </span><span class="s">item</span><span class="nv"> </span><span class="s">}}.d"</span>
    <span class="na">state</span><span class="pi">:</span> <span class="s">directory</span>
    <span class="na">owner</span><span class="pi">:</span> <span class="s">root</span>
    <span class="na">group</span><span class="pi">:</span> <span class="s">root</span>
    <span class="na">mode</span><span class="pi">:</span> <span class="s1">'</span><span class="s">0755'</span>
  <span class="na">loop</span><span class="pi">:</span>
    <span class="pi">-</span> <span class="s">machine.slice</span>
    <span class="pi">-</span> <span class="s">system.slice</span>
    <span class="pi">-</span> <span class="s">user.slice</span>


<span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">Configure machine.slice memory limit</span>
  <span class="na">ansible.builtin.copy</span><span class="pi">:</span>
    <span class="na">dest</span><span class="pi">:</span> <span class="s">/etc/systemd/system/machine.slice.d/50-memory.conf</span>
    <span class="na">content</span><span class="pi">:</span> <span class="pi">|</span>
      <span class="s">[Slice]</span>
      <span class="s">MemoryAccounting=yes</span>
      <span class="s">MemoryHigh={{ (ansible_memtotal_mb - host_reserve_mb - vm_high_headroom_mb) }}M</span>
      <span class="s">MemoryMax={{ (ansible_memtotal_mb - host_reserve_mb) }}M</span>
    <span class="na">owner</span><span class="pi">:</span> <span class="s">root</span>
    <span class="na">group</span><span class="pi">:</span> <span class="s">root</span>
    <span class="na">mode</span><span class="pi">:</span> <span class="s1">'</span><span class="s">0644'</span>
  <span class="na">notify</span><span class="pi">:</span> <span class="s">systemd daemon reload</span>

<span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">Protect host services from VM memory pressure</span>
  <span class="na">ansible.builtin.copy</span><span class="pi">:</span>
    <span class="na">dest</span><span class="pi">:</span> <span class="s">/etc/systemd/system/system.slice.d/50-memory.conf</span>
    <span class="na">content</span><span class="pi">:</span> <span class="pi">|</span>
      <span class="s">[Slice]</span>
      <span class="s">MemoryAccounting=yes</span>
      <span class="s">MemoryMin={{ host_min_mb }}M</span>
      <span class="s">MemoryLow={{ host_low_mb }}M</span>
    <span class="na">owner</span><span class="pi">:</span> <span class="s">root</span>
    <span class="na">group</span><span class="pi">:</span> <span class="s">root</span>
    <span class="na">mode</span><span class="pi">:</span> <span class="s1">'</span><span class="s">0644'</span>
  <span class="na">notify</span><span class="pi">:</span> <span class="s">systemd daemon reload</span>

<span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">Protect user slice services from VM memory pressure</span>
  <span class="na">ansible.builtin.copy</span><span class="pi">:</span>
    <span class="na">dest</span><span class="pi">:</span> <span class="s">/etc/systemd/system/user.slice.d/50-memory.conf</span>
    <span class="na">content</span><span class="pi">:</span> <span class="pi">|</span>
      <span class="s">[Slice]</span>
      <span class="s">MemoryAccounting=yes</span>
      <span class="s">MemoryMin={{ user_min_mb }}M</span>
      <span class="s">MemoryLow={{ user_low_mb }}M</span>
    <span class="na">owner</span><span class="pi">:</span> <span class="s">root</span>
    <span class="na">group</span><span class="pi">:</span> <span class="s">root</span>
    <span class="na">mode</span><span class="pi">:</span> <span class="s1">'</span><span class="s">0644'</span>
  <span class="na">notify</span><span class="pi">:</span> <span class="s">systemd daemon reload</span>

</code></pre></div></div>

<p>Checking the <code class="language-plaintext highlighter-rouge">machine.slice</code> counters a while after applying the fix: <code class="language-plaintext highlighter-rouge">max</code>, <code class="language-plaintext highlighter-rouge">oom</code> and <code class="language-plaintext highlighter-rouge">oom_kill</code> are all zero, so nothing has been killed. The 62k <code class="language-plaintext highlighter-rouge">high</code> events are the throttle doing its job rather than a problem, though they suggest my 1GB of headroom below <code class="language-plaintext highlighter-rouge">MemoryMax</code> is on the tight side. These are cumulative counts since boot, not bytes. Long term, its worth collecting these figures directly, in prometheus.</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c"># 32GB system RAM server</span>
<span class="nv">$ </span><span class="nb">cat</span> /sys/fs/cgroup/machine.slice/memory.events
low 0
high 62467
max 0
oom 0
oom_kill 0
oom_group_kill 0
</code></pre></div></div>

<h2 id="retrospective">Retrospective</h2>
<p>I completed the five-step TODO list over the weekend and systems have been stable all week with no data loss so I’m calling this a success. It remains to be seen if Kubernetes nodes will still crash every couple of months, but I’m pretty sure this particular problem is fixed, without the need to build a glorified AI-enabled cron job to do the occasional reboot.</p>

<p>The Rook/Ceph upgrade was quite an eye opener. It took longer than I would have liked to figure out what was going on, and although there was no data loss, there was an unplanned outage.</p>

<p>Since this is a lab environment, it’s no big deal but if this had been an enterprise system we would now be proceeding with caution. This is why we have dev environments - and <a href="https://rook.io/support">support contracts</a>.</p>

<h2 id="farewell-rookceph">Farewell, Rook/Ceph</h2>

<p>I’ve run this five node Rook/Ceph cluster for over two and a half years now, and it’s worked really well on my 1GbE network.</p>

<p>I’ve been able to reboot or power off nodes without fear and watch Rook/Ceph recover or rebalance itself when <a href="https://docs.ceph.com/en/latest/man/8/ceph-osd/">OSD</a>s are back online. It’s really fun to watch it do this and I’ve learned a lot from running the cluster all this time.</p>

<p>With that said, the upgrade process makes me a little nervous about using Rook/Ceph on a system that needs to be running 24/7 without having additional lab environments to model the upgrade.</p>

<p>Considering I don’t actually have <em>any</em> data I care about in the Rook/Ceph cluster, there’s no justification for building out more environments and doing additional testing for upgrades.</p>

<p>My original plan was to just to try out Rook/Ceph replicated storage in lab environment with my sample crypto servers to see how it works in the real wold and maybe add more workloads if useful.</p>

<p>Now that I’ve completed this research task and hard drive costs have quadrupled, it’s time to shut down Rook/Ceph before it burns out the SSDs for the simple reason that I don’t have a workload to justify using it at the moment:</p>
<ul>
  <li>Crypto node data is replicated at the node level and freely (if slowly) available from the peer-to-peer network. In an enterprise context such as an exchange, the solution needed is multiple independent nodes with their own storage, not “floating” storage</li>
  <li>Messaging systems such as Kafka are best served by local NVMe disks - in my case, the outage I had took all PVs offline at the same time. This would have taken down Kafka if I was running it as its pods would simply not have been able to start. The choke-point of the CSI driver defeats the decentralization of both Ceph and Kafka</li>
  <li>Databases such as postgres are also best served by local NVMe for speed. This removes the network path from all read/write activity</li>
  <li>S3-like storage is a genuine loss, although I don’t currently use this capability and <a href="https://rmoff.net/2026/01/14/alternatives-to-minio-for-single-node-local-s3/">alternatives exist</a></li>
</ul>

<p>Rook/Ceph really shines in environments where the data being stored is actually valuable and there is some tolerance in terms of latency: Think git, documents, backups, etc.</p>

<p>So what do we do instead?</p>
<ul>
  <li><a href="https://openebs.io/docs/user-guides/local-storage-user-guide/local-pv-lvm/lvm-overview">LMV Local PV</a> for capacity limit aware local node storage</li>
  <li>Node Affinity to ensure nodes run adjacent to their storage</li>
  <li>A simple NAS somewhere on the network</li>
  <li>Backups/snapshotting for quick recovery (eg for crypto nodes, same with more safeguards for postgres)</li>
  <li>Assess the storage needs of new workloads on a case-by-case basis</li>
</ul>

<p>If replicated storage requirements come up again in the future, then it’s time to upgrade the network backbone to at least 10GbE, add more PCs for additional environments and re-test <a href="https://longhorn.io/">Longhorn</a> for good measure. I can’t see this happening any time soon though - I already spent a fortune on mini PCs and there are no power sockets left either.</p>

<p>Somewhat ironically, turning off Rook/Ceph will also free up approximately 12GB system RAM on each hypervisor, down from 20GB before this exercise.</p>

<p><em>The very problem we were trying to fix</em>.</p>]]></content><author><name>Geoff Williams</name><email>geoff@declarativesystems.com</email></author><category term="rook" /><category term="ceph" /><category term="homelab" /><category term="nas" /><category term="lvm" /><category term="kubernetes" /><category term="storage" /><category term="architecture" /><category term="upgrades" /><category term="devops" /><summary type="html"><![CDATA[How a routine homelab OOM problem led to a Rook/Ceph and Kubernetes upgrade - and ultimately deciding simpler local storage was the better fit]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="/assets/img/simpsons_no.gif" /><media:content medium="image" url="/assets/img/simpsons_no.gif" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Since when does ping have state?</title><link href="/2026/09/09/python-ping3-session-reuse.html" rel="alternate" type="text/html" title="Since when does ping have state?" /><published>2026-09-09T00:00:00+00:00</published><updated>2026-09-09T00:00:00+00:00</updated><id>/2026/09/09/python-ping3-session-reuse</id><content type="html" xml:base="/2026/09/09/python-ping3-session-reuse.html"><![CDATA[<p>I have a small Python service pinging <code class="language-plaintext highlighter-rouge">8.8.8.8</code> once a second to detect internet outages:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">for</span> <span class="n">host</span> <span class="ow">in</span> <span class="nf">get_config</span><span class="p">().</span><span class="n">ping</span><span class="p">.</span><span class="n">internet_hosts</span><span class="p">:</span>
    <span class="n">result</span> <span class="o">=</span> <span class="n">ping3</span><span class="p">.</span><span class="nf">ping</span><span class="p">(</span><span class="n">host</span><span class="p">,</span> <span class="n">timeout</span><span class="o">=</span><span class="nf">get_config</span><span class="p">().</span><span class="n">ping</span><span class="p">.</span><span class="n">timeout</span><span class="p">)</span>
    <span class="k">if</span> <span class="n">result</span> <span class="ow">is</span> <span class="ow">not</span> <span class="bp">None</span><span class="p">:</span>
        <span class="n">logger</span><span class="p">.</span><span class="nf">debug</span><span class="p">(</span><span class="sh">"</span><span class="s">ping internet OK host=%s</span><span class="sh">"</span><span class="p">,</span> <span class="n">host</span><span class="p">)</span>
        <span class="k">return</span> <span class="n">NetworkCheckResult</span><span class="p">.</span><span class="n">UP</span>
</code></pre></div></div>

<p>I disabled internet access on the router to test this but the pings kept succeeding. What the heck?!</p>

<ul>
  <li>Running <code class="language-plaintext highlighter-rouge">ping 8.8.8.8</code> from the CLI on the same host failed correctly.</li>
  <li>Restarting the Python process made it fail correctly.</li>
  <li>Leaving Python running meant <code class="language-plaintext highlighter-rouge">ping</code> continued to report success</li>
</ul>

<h2 id="firewall-state-table">Firewall state table</h2>

<p>On the OPNsense box:</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code>root@OPNsense:~ <span class="c"># pfctl -ss | grep 8.8.8.8</span>
all icmp 8.8.8.8:8 &lt;- 10.20.86.158:55172       0:0
all icmp 167.179.158.61:19000 <span class="o">(</span>10.20.86.158:55172<span class="o">)</span> -&gt; 8.8.8.8:8       0:0
root@OPNsense:~ <span class="c"># pfctl -F state</span>
2217 states cleared
</code></pre></div></div>

<p>The moment I flushed the states, Python started reporting the outage. So the packets weren’t being evaluated against the firewall rules at all - they were matching an existing state entry created back when the internet still worked, and states are checked before rules.</p>

<p>That explains why blocking had no effect. It doesn’t yet explain why the CLI behaved differently.</p>

<h2 id="python-ping3-stable-icmp-identifiers">Python ping3 stable ICMP identifiers</h2>

<p>pf keys an ICMP state on the identifier field in the echo request. Here’s how <code class="language-plaintext highlighter-rouge">ping3</code> picks that value:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">thread_id</span> <span class="o">=</span> <span class="n">threading</span><span class="p">.</span><span class="nf">get_native_id</span><span class="p">()</span>
<span class="n">process_id</span> <span class="o">=</span> <span class="n">os</span><span class="p">.</span><span class="nf">getpid</span><span class="p">()</span>
<span class="n">icmp_id</span> <span class="o">=</span> <span class="n">zlib</span><span class="p">.</span><span class="nf">crc32</span><span class="p">(</span><span class="sa">f</span><span class="sh">"</span><span class="si">{</span><span class="n">process_id</span><span class="si">}{</span><span class="n">thread_id</span><span class="si">}</span><span class="sh">"</span><span class="p">.</span><span class="nf">encode</span><span class="p">())</span> <span class="o">&amp;</span> <span class="mh">0xffff</span>
</code></pre></div></div>

<p>It’s recomputed on every call, but the inputs never change while the process is alive. So every ping from my long-running service carried the identical identifier.</p>

<p>To pf, that isn’t a thousand separate probes. It’s one continuous flow. The state matched, so the packet skipped rule evaluation - and because traffic kept arriving every second, the state’s idle timer kept resetting and it never aged out.</p>

<p>The CLI behaves differently for a boring reason: each <code class="language-plaintext highlighter-rouge">ping</code> invocation is a new process with a new PID, so it gets a new identifier, matches no existing state, falls through to the actual rules, and gets blocked. Restarting Python works for exactly the same reason.</p>

<p>This identifier scheme isn’t a bug. It exists specifically so that pings from different threads and processes don’t collide with each other. It just happens to interact badly with stateful firewalls when you’re probing on a loop.</p>

<h2 id="the-fix">The fix</h2>

<p><code class="language-plaintext highlighter-rouge">ping3.ping()</code> doesn’t expose an <code class="language-plaintext highlighter-rouge">id</code> parameter:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="p">(</span><span class="n">dest_addr</span><span class="p">,</span> <span class="n">timeout</span><span class="o">=</span><span class="mi">4</span><span class="p">,</span> <span class="n">unit</span><span class="o">=</span><span class="sh">'</span><span class="s">s</span><span class="sh">'</span><span class="p">,</span> <span class="n">src_addr</span><span class="o">=</span><span class="sh">''</span><span class="p">,</span> <span class="n">ttl</span><span class="o">=</span><span class="bp">None</span><span class="p">,</span> <span class="n">seq</span><span class="o">=</span><span class="mi">0</span><span class="p">,</span> <span class="n">size</span><span class="o">=</span><span class="mi">56</span><span class="p">,</span> <span class="n">interface</span><span class="o">=</span><span class="sh">''</span><span class="p">,</span> <span class="n">version</span><span class="o">=</span><span class="bp">None</span><span class="p">)</span>
</code></pre></div></div>

<p>But the functions it calls internally are public and do accept <code class="language-plaintext highlighter-rouge">icmp_id</code>. This is the code I ended up using, which fixes the problem:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kn">import</span> <span class="n">socket</span>
<span class="kn">import</span> <span class="n">random</span>
<span class="kn">import</span> <span class="n">ping3</span>

<span class="k">def</span> <span class="nf">ping_random_id</span><span class="p">(</span><span class="n">dest_addr</span><span class="p">,</span> <span class="n">timeout</span><span class="o">=</span><span class="mi">4</span><span class="p">,</span> <span class="n">size</span><span class="o">=</span><span class="mi">56</span><span class="p">):</span>
    <span class="n">icmp_id</span> <span class="o">=</span> <span class="n">random</span><span class="p">.</span><span class="nf">randint</span><span class="p">(</span><span class="mi">0</span><span class="p">,</span> <span class="mh">0xffff</span><span class="p">)</span>
    <span class="k">with</span> <span class="n">socket</span><span class="p">.</span><span class="nf">socket</span><span class="p">(</span><span class="n">socket</span><span class="p">.</span><span class="n">AF_INET</span><span class="p">,</span> <span class="n">socket</span><span class="p">.</span><span class="n">SOCK_RAW</span><span class="p">,</span> <span class="n">socket</span><span class="p">.</span><span class="n">IPPROTO_ICMP</span><span class="p">)</span> <span class="k">as</span> <span class="n">sock</span><span class="p">:</span>
        <span class="k">try</span><span class="p">:</span>
            <span class="n">sock</span><span class="p">.</span><span class="nf">settimeout</span><span class="p">(</span><span class="n">timeout</span><span class="p">)</span>
            <span class="n">ping3</span><span class="p">.</span><span class="nf">send_one_ping</span><span class="p">(</span><span class="n">sock</span><span class="o">=</span><span class="n">sock</span><span class="p">,</span> <span class="n">dest_addr</span><span class="o">=</span><span class="n">dest_addr</span><span class="p">,</span> <span class="n">icmp_id</span><span class="o">=</span><span class="n">icmp_id</span><span class="p">,</span> <span class="n">seq</span><span class="o">=</span><span class="mi">0</span><span class="p">,</span> <span class="n">size</span><span class="o">=</span><span class="n">size</span><span class="p">)</span>
            <span class="n">delay</span> <span class="o">=</span> <span class="n">ping3</span><span class="p">.</span><span class="nf">receive_one_ping</span><span class="p">(</span><span class="n">sock</span><span class="o">=</span><span class="n">sock</span><span class="p">,</span> <span class="n">icmp_id</span><span class="o">=</span><span class="n">icmp_id</span><span class="p">,</span> <span class="n">seq</span><span class="o">=</span><span class="mi">0</span><span class="p">,</span> <span class="n">timeout</span><span class="o">=</span><span class="n">timeout</span><span class="p">)</span>
        <span class="k">except</span> <span class="nb">Exception</span> <span class="k">as</span> <span class="n">e</span><span class="p">:</span>
            <span class="n">logger</span><span class="p">.</span><span class="nf">debug</span><span class="p">(</span><span class="sh">"</span><span class="s">caught and ignored ping error: %s</span><span class="sh">"</span><span class="p">,</span> <span class="n">e</span><span class="p">)</span>
            <span class="c1"># typically means timeout
</span>            <span class="k">return</span> <span class="bp">None</span>

    <span class="k">return</span> <span class="n">delay</span>  <span class="c1"># seconds
</span></code></pre></div></div>

<h2 id="wont-a-new-id-every-second-flood-the-state-table">Won’t a new ID every second flood the state table?</h2>

<p>ICMP states expire on a short idle timer — the FreeBSD pf defaults are <code class="language-plaintext highlighter-rouge">icmp.first 20s</code> and <code class="language-plaintext highlighter-rouge">icmp.error 10s</code>. If an identifier is never seen again, its state just ages out. So pinging once a second with a fresh id gives you roughly 10–20 concurrent states per monitored host at any instant, constantly being replaced. Across a handful of hosts that’s under a hundred entries, in a table typically sized for hundreds of thousands.</p>

<p>If you want to confirm it for yourself, watch <code class="language-plaintext highlighter-rouge">pfctl -ss | grep icmp | wc -l</code> for a few minutes after the change. It should hover, not climb.</p>

<h2 id="claudes-final-thoughts">Claude’s final thoughts</h2>

<p>A monitoring probe that looks identical to itself on every run is indistinguishable from an established, already-permitted flow. That’s a nice property for real traffic and a terrible one for a health check.</p>

<p>Yes, most of this article was written by Claude. He also did most of the research and troubleshooting. AI slop? You tell me. I wanted to publish my notes in case this comes up again.</p>]]></content><author><name>Geoff Williams</name><email>geoff@declarativesystems.com</email></author><category term="python" /><category term="networking" /><category term="programming" /><category term="opnsense" /><summary type="html"><![CDATA[Python ping3 keeps succeeding when the internet is down (pf/OPNsense state table)]]></summary></entry><entry><title type="html">Designing a PCB for assembly</title><link href="/2026/08/02/designing-pcb-for-assembly.html" rel="alternate" type="text/html" title="Designing a PCB for assembly" /><published>2026-08-02T00:00:00+00:00</published><updated>2026-08-02T00:00:00+00:00</updated><id>/2026/08/02/designing-pcb-for-assembly</id><content type="html" xml:base="/2026/08/02/designing-pcb-for-assembly.html"><![CDATA[<h2 id="why">Why?</h2>

<p>I have a <a href="https://github.com/GeoffWilliams/checkinator">Raspberry Pi Zero W project</a> where I wanted to put a bunch of components inside a small 3D printed enclosure to be left running 24/7. I didn’t want to leave components hanging out of a <a href="https://en.wikipedia.org/wiki/Breadboard">breadboard</a> where they could fall out and this wouldn’t fit either.</p>

<p>I tried building something with <a href="https://en.wikipedia.org/wiki/Perfboard">perfboard</a> but ended up just destroying it due to complex wiring, mistakes and poor soldering technique.</p>

<p>It turns out to be simpler to just learn PCB design with <a href="https://www.kicad.org/">KiCad</a> and have my boards made professionally. For my project, I ended up designing a simple through-hole Raspberry Pi HAT that made the wiring dead simple.</p>

<p>Since this was my first time ever using a PCB manufacturer, I added a couple of other projects to my order to see how far I could push my learning:</p>

<ol>
  <li>A simple <a href="https://en.wikipedia.org/wiki/Through-hole_technology">THT</a> red LED</li>
  <li>A fully assembled <a href="https://en.wikipedia.org/wiki/Surface-mount_technology">SMT</a> <a href="https://www.youtube.com/watch?v=B5eWpRFC9Aw">Buck Converter</a></li>
</ol>

<p>There’s a tenuous relationship between PCB assembly and modern software development that I wanted to explore as part of this exercise as well: In the software world, we hear the term <a href="https://about.gitlab.com/blog/the-ultimate-guide-to-sboms/">SBOM</a> all the time in enterprise IT. I got to <a href="/2026/07/18/java-maven-nvd-sbom.html">experience this for myself recently</a>. The <a href="https://en.wikipedia.org/wiki/Bill_of_materials">BOM</a> concept itself is rooted in physical manufacturing and a good practical example is PCB assembly. If you are trying to use a PCB assembly service, you will need to produce a BOM as well as some other files.</p>

<p>Let’s try out <a href="https://jlcpcb.com/">JLCPCB</a> assembly service and see if we can get something working.</p>

<h2 id="the-project">The project</h2>

<p>I picked a 5V USB-C to 3.3V buck converter. It’s a great first project since:</p>
<ul>
  <li>Any electrical engineer understands what I’m trying to build</li>
  <li>Cheap and readily available components</li>
  <li>Complex enough to present a challenge, but high likelihood of success</li>
  <li>Results in a genuinely useful circuit board. I’m planning on using mine next Christmas to replace battery packs on my LED lights</li>
</ul>

<h2 id="the-process">The Process</h2>

<h3 id="step-1---learn-kicad">Step 1 - Learn KiCad</h3>

<p>The <a href="https://www.kicad.org/">KiCad</a> software itself is outstanding and also Free Software (GPLv3). It’s not as hard to use as <a href="https://www.autodesk.com/products/fusion-360/overview">Fusion 360</a> but it does have its own learning curve. For a simple project like this one you could just use “normal” CAD but a specialist tool like KiCad is 100% worth learning as an investment in your own skills and understanding.</p>

<p>There is a lot more to it than this but rough steps needed in KiCad are:</p>
<ol>
  <li>Schematic design</li>
  <li>PCB design</li>
  <li>Design Rules Check</li>
  <li>Export</li>
</ol>

<h3 id="step-2---research-design-and-component-selection">Step 2 - Research, design and component selection</h3>
<p>I spent a lot of time up-front researching how buck converters work and came up with an initial design:</p>

<p><img src="/assets/img/buckconverter_3d_v0.png" alt="initial design" /></p>

<p>To pick components, I used the <a href="https://jlcpcb.com/parts">JLCPCB parts catalog</a> and leaned on ChatGPT <strong>a lot</strong> for validation.</p>

<p>To do the PCB design, I needed accurate <a href="https://www.pcbx.com/article/What-is-SMT-Footprint">footprints</a> so I signed up for EasyEDA (click through while browsing parts) to download the files for the parts I needed. This is much more convenient and less error prone than <a href="https://learn.pcbcupid.com/pcb-design/design/kicad/custom-footprints-in-kicad">designing your own footprints</a>.</p>

<p>I ended up with a directory of parts I like to use in my <code class="language-plaintext highlighter-rouge">$HOME</code> set as an external library via the <code class="language-plaintext highlighter-rouge">Footprint Editor</code> and was then able to use my exact components for board design.</p>

<h3 id="step-3---design-validation">Step 3 - Design validation</h3>

<p>At this point, I could have had the board manufactured, but I wanted to increase my odds of getting it right first time so I <a href="https://www.eevblog.com/forum/beginners/beginner-pcb-design-help-lm2596-buck-converter/msg5689195/">posted a message on EEVblog</a> asking for help. If you haven’t come across <a href="https://www.eevblog.com/">EEVblog</a> before, it’s THE place to talk to passionate electrical engineers.</p>

<p>A couple of days later, I had some really helpful responses and adjusted my design a bit. Reassuringly (and somewhat surprisingly), no one said it was broken at the design level. At this point this project got put on hold <em>for a couple of years</em>.</p>

<h3 id="step-4---export-upload-order">Step 4 - Export, upload, order</h3>

<p>The files needed for manufacturing follow exact formats and are largely based around CSV. They are used for etching, drilling, pick-and-place, etc and they drive the entire manufacturing process. Designers normally produce a zip file containing <a href="https://jlcpcb.com/help/catalog/180-PCB-Files-Preparation">Gerber files</a>, <a href="https://jlcpcb.com/help/catalog/190-PCBA-Files-Preparation">BOM, and Pick-and-Place files</a>.</p>

<p>Following these links leads to a maze of different file formats, export procedures and gotchas. Any of which are capable of blocking manufacturing or worse.</p>

<p>Automating export in the right format for your chosen manufacturer reduces the opportunity for mistakes and speeds up the process too. After some research I settled on using <a href="https://github.com/bennymeg/Fabrication-Toolkit">Fabrication Toolkit</a>. This KiCad plugin basically produces all of the above files in the correct format in just a few clicks. They can then be uploaded directly for manufacture as a <code class="language-plaintext highlighter-rouge">.zip</code>.</p>

<p>After a final <a href="https://jlcpcb.com/blog/how-to-run-design-rule-check">Design Rules Check</a>, I uploaded the files, got a quote and did a couple of “fixes” which bit me a few hours later:</p>
<ol>
  <li>I had to change a couple of parts due to stock availability</li>
  <li>Holes must be listed in the BOM. Pretty sure I cheated and just added directly to the CSV file:</li>
</ol>

<pre><code class="language-csv">H1,MountingHole_3mm,1,Mechanical hole,N/A
H2,MountingHole_3mm,1,Mechanical hole,N/A
H3,MountingHole_3mm,1,Mechanical hole,N/A
H4,MountingHole_3mm,1,Mechanical hole,N/A
</code></pre>

<p>Then I hit the <code class="language-plaintext highlighter-rouge">Order</code> button.</p>

<h2 id="questions-from-the-factory">Questions from the factory</h2>

<p>A little while after ordering I received some questions from the factory in a very polite email:</p>

<blockquote>
  <p>Dear customer,</p>

  <p>Well got your order with many thanks.</p>

  <p>Sorry to bother you, but there is one thing that we want to confirm with you about your PCBA order [REMOVED] before proceeding.</p>

  <p>1. As shown below, seems the packages of the parts ( C2) cannot match the corresponding footprint on the PCB board.</p>

  <p>We have activated the “Replace Part” button for you. Please change the part on your order history. If you want to leave the designator unpopulated, just unclick the “Select” for this part.</p>

  <p>Please kindly note that we cannot replace the file directly for PCBA order. If you want to change the gerber file, we need to cancel the order, then you place new order with new file.</p>

  <p>2. As shown below, seems the packages of the parts ( J2) cannot match the corresponding footprint on the PCB board.  There’s risk of weak connection, bad soldering, tombstoning. We have 4 suggestions for you.  Please make a choice.</p>

  <p>A: Open the access of “replace parts” for you to change part on order history.</p>

  <p>B: Leave the mismatched part unpopulated and refund and cost of part. We cannot ship the unpopulated part to customer due to customs clearance issue.</p>

  <p>C: Cancel the order for you to redesign the footprint on PCB. Because we cannot replace the file directly for PCBA order. If you want us to refund the payment to JLC balance(not available if customer pay in EUR €). Please set the JLC balance in your account.  https://jlcpcb.com/help/article/how-to-set-up-refunds-to-jlc-balance</p>

  <p>D: Take the risk to solder the current component and will not complaint.</p>

  <p>Your early reply will be highly appreciated, thank you so much!</p>

  <p>Best regards,
JLCPCB Team</p>
</blockquote>

<p>Capacitor footprint:</p>

<p><img src="/assets/img/jlcpcb_bad_footprint_1.png" alt="bad footprint #1" /></p>

<p>Jumper footprint:</p>

<p><img src="/assets/img/jlcpcb_bad_footprint_2.png" alt="bad footprint #2" /></p>

<p>It turns out I selected a replacement capacitor that looked the same to my novice eye but had a different footprint. The header pins were also completely different.</p>

<p>Finding in-stock replacements matching the submitted design files was actually the hardest part of this entire project. Matching the KiCad generic footprint <code class="language-plaintext highlighter-rouge">Connector_PinHeader_2.54mm:PinHeader_1x02_P2.54mm_Vertical_SMD_Pin1Left</code> to an exact JLCPCB part was not (for me at least) a quick and easy process. After an intense help session with ChatGPT, I settled on <a href="https://jlcpcb.com/partdetail/DEALON-DZ254S_11_0248/C5160785"><code class="language-plaintext highlighter-rouge">C5160785</code></a> as a replacement.</p>

<p>The next day, I got another very polite email:</p>

<blockquote>
  <p>Dear customer,</p>

  <p>Sorry to bother you.</p>

  <p>For C9939, we are currently short of 5 pieces for the assembly of this order.</p>

  <p>Sorry for the inconvenience. May I ask if you need to replace it with other components? If so, could you check if there is some replacement available in our parts lib? https://jlcpcb.com/parts/</p>

  <p>Looking forward to hearing from you.</p>

  <p>Best regards,</p>

  <p>JLCPCB Team</p>
</blockquote>

<p>I settled on <a href="https://jlcpcb.com/partdetail/73539-SMSD1306470MT/C72428">C72428</a> <code class="language-plaintext highlighter-rouge">2.6A 4.5A 47uH 86mΩ Unshielded Inductor ±20% SMD,18.5x15.2mm Power Inductors ROHS</code> as a replacement part.</p>

<p>Interestingly, the replacement selection at this stage was just done via email instead of the replacement part flow. Presumably this means if I click the re-order button this final change would likely not have been captured. This is probably “fine” for small projects when parts come back into stock but results in a materially different board. This is a problem if you are trying to test, scale or certify a product.</p>

<p>In the software world, we call this <a href="https://reproducible-builds.org/">Reproducible Builds</a> - eg, do I get the exact same board with the same components if I click <code class="language-plaintext highlighter-rouge">Reorder</code>. I highly doubt that in this case, so due diligence means updating the KiCad files with the replacement choices that were made. A more robust approach would have been to cancel the order at the first email, fix the design and resubmit. This proves that all changes have been captured accurately.</p>

<p>Thankfully, the next and final email I received from JLCPCB was a shipping notification.</p>

<h2 id="did-it-work">Did it work?</h2>

<h3 id="simple-led-pcb">Simple LED PCB</h3>
<p>First I assembled the through-hole LED. Hooking up 2x AA batteries made the light come on:</p>

<p><img src="/assets/img/jlcpcb_simple_led.jpg" alt="Simple LED" /></p>

<h3 id="checkinator">“Checkinator”</h3>
<p>The through-hole “checkinator” Raspberry Pi hat also looked great, although I goofed the silkscreening and missed some vital labels. More on this project board another day:</p>

<p><img src="/assets/img/jlcpcb_checkinator.jpg" alt="checkinator" /></p>

<h3 id="buck-converter">Buck Converter</h3>

<ul>
  <li><strong>FIRE DANGER, especially with loads &gt; 1A</strong>
    <blockquote>
      <p>Also D1 looks a bit small, I think it may get too hot. 
Definitely not going to get 3A output with a 3A diode. I’d go with 6A and in a larger package, like SMC.
But ok to test with a 3A diode if the output current is kept at like 1A or so</p>
    </blockquote>
  </li>
  <li>I don’t suggest that anyone attempts to manufacture this board from my KiCad files</li>
  <li>Note intended application: Power small LED string normally driven by 2x AA batteries</li>
</ul>

<p>The buck converter board also looked great. All parts were securely attached and everything was neat and tidy.</p>

<p><img src="/assets/img/jlcpcb_buck_converter.jpg" alt="buck converter pcba" /></p>

<p>The final part of this saga was to crimp dupont connectors onto my old LED battery pack lights and hook-up a laptop USB-C power supply. To my surprise it worked:</p>

<p><img src="/assets/img/jlcpcb_buck_leds_working.jpg" alt="it works!" /></p>

<p>I left it plugged in for hours, nothing got hot and it didn’t burn <strong>my</strong> house down. All 3 designs worked. I call this a success!</p>

<p>After cranking out a <a href="https://www.printables.com/model/1797686-simple-electronics-enclosure">3D printed case in Fusion 360</a> and spending an afternoon assembling cases, I’m now all set for Christmas 2026. I have five of these circuit boards since that’s the minimum order quantity. All boards were tested and worked.</p>

<p><img src="/assets/img/jlcpcb_done.jpg" alt="all done" /></p>

<h2 id="how-much-did-it-cost">How much did it cost?</h2>

<p>The total order came to about $100 USD and about 30% of this cost was DHL shipping to Australia:</p>

<p><img src="/assets/img/jlcpcb_invoice.jpg" alt="invoice extract" /></p>

<p>The PCB assembly service <em>is</em> a lot more expensive than just producing a bare PCB. In my case the extra cost is worth it vs doing a fiddly job on the kitchen bench. I’m positive that putting effort into choosing cheaper parts would have brought down the cost considerably too.</p>

<p>The caveat is that with an MOQ of 5, if you just want a single assembled board, you need to pay 5x the cost vs what you actually want. For a bare PCB this waste can be under $1 per board but an assembled PCB is orders of magnitude more expensive and becomes cost-prohibitive once you’re beyond the realm of “toy” projects.</p>

<h2 id="how-long-did-it-take">How long did it take?</h2>

<ul>
  <li>Fabrication, including all correspondence, took under 6 days. Production was blocked waiting for response from me for around 4 hours total</li>
  <li>DHL Shipping to NSW, Australia took 3 days: Posted Saturday night, arrived first thing Tuesday morning</li>
  <li>Less than 9 days to go from design upload to boards in-hand. Order was made on a Sunday afternoon</li>
</ul>

<h2 id="what-did-i-learn">What did I learn?</h2>

<p><strong>This is a learning exercise, not a useful product</strong></p>

<p>The discussion on EEVblog continued while I got caught up in a ton of side quests for a couple of years, highlighting some changes that would make a better board.</p>

<p>At least one forum reply talked about excessive heat and therefore <strong>FIRE DANGER</strong>, although this seems to be more in connection with higher loads vs intended use of small string of LEDs. RF noise was also mentioned, so it’s likely this little board could cause a nuisance or worse.</p>

<p>In my own testing, nothing measured more than 5C above ambient temperature after an hour or so, but I’m still loath to leave these <em>Christmas Lights</em> unattended in case of returning to a nasty surprise (fire), although everything “seems fine”.</p>

<p>One of the main things I learned in this process was just how nice the assembly service is.</p>

<p>My soldering technique has <a href="https://groups.google.com/g/pidp-11/c/ue9SmMnIqlE?pli=1">caused me big problems</a> in the last couple of years. It’s hard for me to do since I don’t have a dedicated workspace, microscope, etc and if I’m honest, I don’t even particularly enjoy doing it either.</p>

<p>Next time I have a requirement for something beyond <a href="https://github.com/geoffWilliams/formpie">a mess of dupont connectors</a> and <a href="https://en.wikipedia.org/wiki/I2C">I2C</a>, I would consider an assembly service without hesitation.</p>

<p>Additional lessons:</p>
<ul>
  <li>Read and re-read any relevant datasheets</li>
  <li>Check footprints carefully</li>
  <li>Don’t trust AI-recommended replacement parts. It’s very hard even for humans to download an accurate footprint, so ChatGPT and Claude have no chance</li>
  <li>For projects you care about, it’s best to cancel and resubmit designs so footprints can be more easily checked in KiCad and all changes captured</li>
</ul>

<h2 id="how-does-real-manufacturing-relate-back-to-sbom">How does real manufacturing relate back to SBOM?</h2>

<p>For the nerds reading this: There are some subtle but important differences.</p>

<p>The design files that get uploaded to a manufacturer are used to literally drive the production process. The CSV BOM files are used to select individual components for pick-and-place, etc. Our SBOM actually does the opposite - it’s the libraries our build tool identified <em>during</em> the build process.</p>

<p>At least in the world of Java development, <a href="https://maven.apache.org/">Maven</a> uses <a href="https://maven.apache.org/pom.html"><code class="language-plaintext highlighter-rouge">pom.xml</code></a> to drive the build process. Resolving <a href="https://maven.apache.org/guides/introduction/introduction-to-dependency-mechanism.html">Dependencies between libraries</a> (eg library <code class="language-plaintext highlighter-rouge">A</code> requires libraries <code class="language-plaintext highlighter-rouge">B</code>, <code class="language-plaintext highlighter-rouge">C</code> and <code class="language-plaintext highlighter-rouge">D</code>) is a key Maven feature and this concept simply doesn’t exist when using the PCB assembly service: You don’t include an <a href="https://en.wikipedia.org/wiki/Integrated_circuit">IC</a> in a BOM and automatically get a bunch of resistors and diodes included - you have to specify exactly what parts you want to use up-front.</p>

<p>On the manufacturing side, the inverse is true: We can produce boards with parts <em>not</em> in the BOM, with replacement parts discussed on an email thread. It’s really up to the designer to handle this process diligently if it’s important for a project.</p>

<p>With that said, SBOM is a sound security and business continuity practice as <strong>part of</strong> producing secure software. Most programmers don’t know or care about such subtleties, but taking the time to manufacture something from scratch has been a fascinating glimpse into how real-world terms get appropriated by the software industry.</p>

<h2 id="where-are-the-design-files">Where are the design files?</h2>

<ul>
  <li><a href="https://github.com/GeoffWilliams/usb_buck_converter">KiCad files</a></li>
  <li><a href="https://www.printables.com/model/1797686-simple-electronics-enclosure">3D printed enclosure</a></li>
</ul>

<h2 id="thanks-and-acknowledgements">Thanks and Acknowledgements</h2>

<p>My sincerest thanks to everyone who responded to my forum post, especially <code class="language-plaintext highlighter-rouge">mareks</code>, and to <code class="language-plaintext highlighter-rouge">Mia</code> and <code class="language-plaintext highlighter-rouge">Angel</code> at JLCPCB for the help with my order.</p>

<p>This post is not sponsored. I paid for my circuit boards with my own money.</p>

<h2 id="eevblog-forum-post">EEVblog forum post</h2>

<p>For posterity, my original post:</p>

<blockquote>
  <p>Hi,</p>

  <p>I’ve been trying to teach myself basic PCB design so that I can make myself a little Raspberry Pi hat to flash some lights. After spending the weekend burning protoboard I decided it would be easier and better to just dive in to PCB design. I don’t have an electronics or maths background but I’ve watched a lot of youtube and have learnt the basics of Kicad after work this week.</p>

  <p>So far I made a little LED through-hole board which has a good chance of working on first attempt but I wanted something a little more challenging before returning to my original problem. I have some LED Christmas lights that take 2x AA batteries and I had already looked at buying a USB buck convertor to step down 5v to 3.3v for these off Aliexpress but I decided to build my own for practice instead.</p>

  <p>I was hoping someone on this forum could tell me if my learning/design process is on the right lines and ideally have a quick look at the PCB I designed and tear it to shreds - that’s how you learn right.</p>

  <p>What I’ve tried so far:</p>

  <ol>
    <li>Random youtube videos on Kicad</li>
    <li>Stay up late tooling round and building that Raspberry Pi hat. I created a PCB that I’m 99% sure would not work at all as some pins marked 3.3V on the schematic were somehow all 5V in PCB designer. Pretty sure I shorted something. Give up and go back to basics</li>
    <li>Design a little LED circuit. Looks good, I’m going to make this</li>
    <li>Spend focussed time learning about Kicad on youtube. The best vids I found were from “PCB Cupid”</li>
    <li>Get a good explanation of what a buck converter is so I know what I’m building <a href="https://www.youtube.com/watch?v=B5eWpRFC9Aw">https://www.youtube.com/watch?v=B5eWpRFC9Aw</a></li>
    <li>Lots of googling for buck converter circuits. Found one that looked easy but also nothing like what Louis explained. That’s because it was just a voltage regulator and I would have built the wrong circuit if I hadn’t done some research</li>
    <li>Found the TI LM2596 SIMPLE SWITCHER referenced in a few places and decided to use this. Read the datasheet and tried to build the circuit listed under “Typical Application”. This is for 5v though, not 3.3v. According to Chat GPT I can just change the IC to the 3.3v version and leave the inductor and capacitors at the same value. Find missing components on snapeda and import into Kicad</li>
    <li>Design a schematic and add USB-C power connector with the CC pins grounded through 5.1K resistors. Electrical Rules Check passing</li>
    <li>I want to have this board fully assembled with SMD components by JLCPCB but the diode and coil parts from datasheet are not in stock on <a href="https://jlcpcb.com/parts/all-electronic-components">https://jlcpcb.com/parts/all-electronic-components</a> so I spent more time looking at specs that I barely understand and then asking Chat GPT if my substitution is OK</li>
    <li>Build PCB from schematic, not fully happy with it</li>
    <li>Do some research on PCB design, Read Dave’s book: <a href="https://www.scs.stanford.edu/~zyedidia/docs/pcb/pcb_tutorial.pdf">https://www.scs.stanford.edu/~zyedidia/docs/pcb/pcb_tutorial.pdf</a>, watch some EEVBLOG vids</li>
    <li>Delete PCB and start again. Try to layout components like the datasheet says, add big traces and copper fill areas. Design Rules Check passing</li>
  </ol>

  <p>I’ve learnt a lot in this process. My overall goal is just to be able to make simple PCBs for Raspberry Pi or other simple circuits for fun, in the future. I’m not planning on changing careers or building really complicated things.</p>

  <p>So on to my questions:</p>

  <p>Components OK?</p>
  <ul>
    <li>33uH inductor AIAP-02-330K</li>
    <li>Input capacitor 680uF EEE-FK1J681AM</li>
    <li>Output capacitor 220uF TPSE227M016R0100</li>
    <li>Diode 30V 3A SS33 (THT - could not find an in-stock SMD one)</li>
    <li>Apart from the USB connector, I only built what was in the datasheet. Is anything else required?
      <ul>
        <li>All good for intended application?: Connect to old phone charger and hook up a small LED string and possibly any other random low power 3.3V DC needs in the future</li>
        <li>What are the chances of my PCB design working?</li>
      </ul>
    </li>
  </ul>

  <p>I haven’t had anything made yet so just asking for any suggestions before I see if this blows up. :-DD</p>

  <p>Thanks for reading all this!</p>

  <p>Cheers,
Geoff</p>
</blockquote>]]></content><author><name>Geoff Williams</name><email>geoff@declarativesystems.com</email></author><category term="hardware" /><category term="pcb" /><category term="design" /><category term="manufacturing" /><category term="education" /><category term="sbom" /><summary type="html"><![CDATA[My first PCB assembly project - learning KiCad, designing a buck converter, navigating manufacturing gotchas, and discovering what SBOMs have to do with hardware.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="/assets/img/jlcpcb_buck_converter.jpg" /><media:content medium="image" url="/assets/img/jlcpcb_buck_converter.jpg" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Growing VirtualBox disks (Linux)</title><link href="/2026/07/18/growing-virtualbox-disks.html" rel="alternate" type="text/html" title="Growing VirtualBox disks (Linux)" /><published>2026-07-18T00:00:00+00:00</published><updated>2026-07-18T00:00:00+00:00</updated><id>/2026/07/18/growing-virtualbox-disks</id><content type="html" xml:base="/2026/07/18/growing-virtualbox-disks.html"><![CDATA[<p>VirtualBox makes the perfect AI playground, but sooner or later you will likely hit the dreaded <code class="language-plaintext highlighter-rouge">No space left on device</code> error.</p>

<p>Here’s how to fix it:</p>

<h2 id="step-1---shutdown-vm">Step 1 - shutdown VM</h2>

<p>Needs to be powered off, not suspended</p>

<h2 id="step-2---grow-the-disk-with-vboxmanage">Step 2 - Grow the disk with <code class="language-plaintext highlighter-rouge">VBoxManage</code></h2>

<p>Find the VDI, then use <code class="language-plaintext highlighter-rouge">VBoxManage</code> to resize it (Example: grow to 50GB):</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c"># megabytes</span>
VBoxManage modifymedium disk debian<span class="se">\ </span>13.vdi <span class="nt">--resize</span> 51200
</code></pre></div></div>

<p>Output:</p>
<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>0%...10%...20%...30%...40%...50%...60%...70%...80%...90%...100%
</code></pre></div></div>

<p>This of course assumes you are using dynamically allocated disk images. If you opted for fixed image sizes, you will need to clone the whole drive to a new, growable image first as the command above would just error out in this case.</p>

<h2 id="step-3---grow-the-disk-in-linux">Step 3 - Grow the disk in Linux</h2>

<h3 id="warning-on-snapshots">Warning on snapshots</h3>
<p>Resizing a disk that has snapshots can behave unexpectedly (the resize applies to the base image, not the current state). Delete/merge your snapshots first - you have been warned.</p>

<h3 id="lvm">LVM</h3>
<p>If you used LVM when setting up your VM, you can follow my notes to <a href="/2023/07/23/growing-ext4-lvm-filesystem-to-use-all-free-space.html">grow the LV holding your root filesystem</a>. Job Done.</p>

<h3 id="growpart">growpart</h3>
<p>If you’re not using LVM and are also “lucky”, you can use <code class="language-plaintext highlighter-rouge">growpart</code> to expand a single <code class="language-plaintext highlighter-rouge">EXT2/3/4</code> partition, like this (see also <code class="language-plaintext highlighter-rouge">xfs_growfs</code> for XFS):</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nb">sudo </span>apt <span class="nb">install </span>cloud-guest-utils
<span class="nb">sudo </span>growpart /dev/sda 2
<span class="nb">sudo </span>resize2fs /dev/sda2
</code></pre></div></div>

<p>However, this relies on contiguous free space. If you have other partitions “in the way”, you will need to move them to the start/end of the drive with <code class="language-plaintext highlighter-rouge">gparted</code> first. Read on.</p>

<h3 id="gparted">gparted</h3>

<p>You can’t move the partitions you need to with <code class="language-plaintext highlighter-rouge">gparted</code> from the running system - you will need to boot into live OS and run <code class="language-plaintext highlighter-rouge">gparted</code> against the unmounted drive instead.</p>

<p>The easiest live environment I have found is <a href="https://ubuntu.com/download/desktop">Ubuntu Desktop</a>. Boot into the live environment and gparted will be right there as an app.</p>

<p>To boot Ubuntu Live DVD instead of your normal Linux:</p>
<ol>
  <li>Download the <code class="language-plaintext highlighter-rouge">.iso</code></li>
  <li>In VirtualBox, choose <code class="language-plaintext highlighter-rouge">VM Settings</code> -&gt; <code class="language-plaintext highlighter-rouge">Storage</code>, then insert the <code class="language-plaintext highlighter-rouge">.iso</code> into virtual CD drive (add one if missing). Don’t check the <code class="language-plaintext highlighter-rouge">Live CD</code> box as this will prevent ejecting the CD at the end of the process</li>
  <li>Boot order in same settings dialog should boot the CD first by default. If not, fix this now</li>
  <li>Boot the VM, <code class="language-plaintext highlighter-rouge">Try or Install Ubuntu</code>, wait a few mins for the OS to load, errors about unsupported graphics can <em>probably</em> (but not necessarily) be ignored, as long as things are still moving on the boot screen</li>
  <li>Click <code class="language-plaintext highlighter-rouge">Next</code> to select Language, Keyboard, Network (wired since it’s a VM), etc until you get to <code class="language-plaintext highlighter-rouge">What do you want to do with Ubuntu?</code>. Change the selection to <code class="language-plaintext highlighter-rouge">Try Ubuntu</code> and click <code class="language-plaintext highlighter-rouge">Close</code></li>
  <li>Now you should be dropped to the desktop. Click the funny 3 dot circle (app grid) in the bottom left of the screen to bring up the apps menu, start typing <code class="language-plaintext highlighter-rouge">gparted</code> click the app icon and then authorize running as root by clicking <code class="language-plaintext highlighter-rouge">Authenticate</code> on the next dialogue</li>
  <li>Good old <code class="language-plaintext highlighter-rouge">gparted</code> should now be running. Make sure to select the correct device, then move and adjust your filesystems as required to use the new space. If you have a <code class="language-plaintext highlighter-rouge">swap</code> partition, you may need to right click -&gt; <code class="language-plaintext highlighter-rouge">swapoff</code> it, to avoid the live CD sneakily using it and stopping you resizing things.</li>
  <li>Finish up in <code class="language-plaintext highlighter-rouge">gparted</code>, then shutdown the system with the menu in top right corner. The CD will automatically be ejected when you hit <code class="language-plaintext highlighter-rouge">enter</code> as prompted</li>
  <li>Power-on the VM, login and check you have some free space with the <code class="language-plaintext highlighter-rouge">df</code> command.</li>
</ol>

<p>Final word of warning: If <code class="language-plaintext highlighter-rouge">gparted</code> offers to fix the GPT layout, say yes.</p>

<p><em>And now back to our AI enhanced sandbox.</em></p>]]></content><author><name>Geoff Williams</name><email>geoff@declarativesystems.com</email></author><category term="linux" /><category term="virtualbox" /><category term="storage" /><category term="devops" /><summary type="html"><![CDATA[How to grow a Linux VirtualBox disk when your VM runs out of space, from VBoxManage through LVM, growpart, and gparted]]></summary></entry><entry><title type="html">Java and Maven - NVD and SBOM</title><link href="/2026/07/18/java-maven-nvd-sbom.html" rel="alternate" type="text/html" title="Java and Maven - NVD and SBOM" /><published>2026-07-18T00:00:00+00:00</published><updated>2026-07-18T00:00:00+00:00</updated><id>/2026/07/18/java-maven-nvd-sbom</id><content type="html" xml:base="/2026/07/18/java-maven-nvd-sbom.html"><![CDATA[<h2 id="tldr">TL;DR</h2>
<p>Maven NVD scanning is broken due to NIST NVD infrastructure, build an SBOM instead and gate the build with Grype or some other tool/process.</p>

<h2 id="q-why-was-i-up-all-night-yesterday">Q: Why was I up all night yesterday?</h2>

<ul>
  <li>A1: Maven</li>
  <li>A2: I wasted hours of my day trying to scan my code with <a href="https://dependency-check.github.io/DependencyCheck/dependency-check-maven/index.html"><code class="language-plaintext highlighter-rouge">dependency-check-maven</code></a></li>
</ul>

<h2 id="q-what-is-dependency-check-maven">Q: What is <code class="language-plaintext highlighter-rouge">dependency-check-maven</code></h2>

<ul>
  <li>A: It’s a Maven plugin to scan for dependencies with <a href="https://en.wikipedia.org/wiki/Common_Vulnerabilities_and_Exposures">CVEs</a>, with the power to fail builds if severity is high enough</li>
</ul>

<h2 id="nist-nvd-service---outage">NIST NVD Service - outage</h2>

<p>All joking aside, at least yesterday, the <a href="https://nvd.nist.gov/">NIST NVD service</a> <code class="language-plaintext highlighter-rouge">dependency-check-maven</code> relies on is just hopelessly broken. Downloading without an API key takes <em>hours</em>, if it works at all.</p>

<p>Yesterday, only approx 15% of the database was downloaded after a couple of hours.</p>

<p>At this point, I caved and <a href="https://nvd.nist.gov/developers/request-an-api-key">requested an API key</a>. Even this process took about half an hour, with multiple failures before a working API key was released.</p>

<p>I’ll save you the trouble of fighting for an API key: On my workstation at least, the database downloaded just as slowly as without a key at all. In fact, leaving Maven trying to download the NVD database with a valid key resulted in a <code class="language-plaintext highlighter-rouge">50x</code> error from the server after an hour or so, with the same result after several attempts.</p>

<p>Best-practice is to <a href="https://dependency-check.github.io/DependencyCheck/data/mirrornvd.html">setup a local (corporate) mirror of NVD</a>, however:</p>
<ul>
  <li>There are no actual instructions on how to do so, just a rough outline of the components needed</li>
  <li>Even if there were, it relies on upstream NVD server working for the initial download</li>
</ul>

<p>I’m pretty sure that for every team who diligently figures out correct mirroring, there’s another ten who just let their CI servers rip on the NVD upstream servers 24/7 for git pushes, so here we are with an NVD system that’s under so much load it’s unusable.</p>

<p>In reality, few developers will fight through all of this to scan their dependencies for CVEs, so the outcome is skipped tests and/or permanently removed security checks from build pipelines.</p>

<h2 id="solution-sbom">Solution? SBOM</h2>

<p>This is not an isolated outage, the NVD service has been failing for a while now. To prevent Maven build failures, there’s really no option but to disable/remove the plugin unless you’re hosting your own NVD mirror.</p>

<p>So what do we do instead? Many developers are turning to Software Bill of Materials - <a href="https://www.ibm.com/think/topics/sbom">SBOM</a>.</p>

<p>In the case of a Java Maven app, this means capturing the full dependency tree. There’s a plugin for this: <a href="https://github.com/CycloneDX/cyclonedx-maven-plugin"><code class="language-plaintext highlighter-rouge">cyclonedx-maven-plugin</code></a>.</p>

<p>Adding the plugin to your Maven project results in capturing dependency information as JSON and XML under the <code class="language-plaintext highlighter-rouge">/target</code> directory.</p>

<p>Now just hand over your favourite flavour of structured data file to your <em>security scanner/team</em> and deploy as usual right?</p>

<p>If you have a true enterprise build and deploy CI pipeline, with integrated SBOM check before deployment, then yes, you may actually be finished - otherwise, you may just be giving yourself a false sense of security.</p>

<p>The great thing about <code class="language-plaintext highlighter-rouge">dependency-check-maven</code> is that it fails the build if severe enough CVEs are detected, and you would have to consciously disable the check to produce a <code class="language-plaintext highlighter-rouge">.jar</code> file. With <em>just</em> SBOM generation, you have a list of libraries but the build will still produce executables <em>unless</em> you add something to your build to act on this information.</p>

<p>To put it another way, just <em>producing</em> the SBOM does not magically improve security posture, you must act on this data somehow.</p>

<h2 id="grype">Grype</h2>

<p>Enter <a href="https://github.com/anchore/grype">Grype</a>:</p>

<blockquote>
  <p>A vulnerability scanner for container images and filesystems.</p>
</blockquote>

<p>Grype has built-in support for reading SBOM files created by <code class="language-plaintext highlighter-rouge">cyclonedx-maven-plugin</code>. It’s approximately five years old, so still somewhat new. Apply your due diligence to determine whether Grype is right for your own organisation.</p>

<h2 id="worked-example">Worked Example</h2>

<p>Aim: Integrate Grype into a project with multiple high-severity CVEs and force build failure at the Maven <code class="language-plaintext highlighter-rouge">package</code> phase.</p>

<h3 id="step-1---simple-java-app">Step 1 - Simple Java app</h3>

<p>I created a simple Maven Java project from scratch with <a href="https://cursor.com/">Cursor</a> featuring just a simple CLI app. It works great:
<img src="/assets/img/cursor_wargames_app.png" alt="wargames app" /></p>

<h3 id="step-2---sbom">Step 2 - SBOM</h3>

<p>Enable SBOM creation during Maven <code class="language-plaintext highlighter-rouge">package</code> phase in <code class="language-plaintext highlighter-rouge">pom.xml</code>:</p>

<div class="language-xml highlighter-rouge"><div class="highlight"><pre class="highlight"><code>            <span class="nt">&lt;plugin&gt;</span>
                <span class="nt">&lt;groupId&gt;</span>org.cyclonedx<span class="nt">&lt;/groupId&gt;</span>
                <span class="nt">&lt;artifactId&gt;</span>cyclonedx-maven-plugin<span class="nt">&lt;/artifactId&gt;</span>
                <span class="nt">&lt;version&gt;</span>2.9.2<span class="nt">&lt;/version&gt;</span>
                <span class="nt">&lt;executions&gt;</span>
                    <span class="nt">&lt;execution&gt;</span>
                        <span class="nt">&lt;id&gt;</span>cyclonedx-bom<span class="nt">&lt;/id&gt;</span>
                        <span class="nt">&lt;phase&gt;</span>package<span class="nt">&lt;/phase&gt;</span>
                        <span class="nt">&lt;goals&gt;</span>
                            <span class="nt">&lt;goal&gt;</span>makeBom<span class="nt">&lt;/goal&gt;</span>
                        <span class="nt">&lt;/goals&gt;</span>
                    <span class="nt">&lt;/execution&gt;</span>
                <span class="nt">&lt;/executions&gt;</span>
                <span class="nt">&lt;configuration&gt;</span>
                    <span class="nt">&lt;projectType&gt;</span>application<span class="nt">&lt;/projectType&gt;</span>
                    <span class="nt">&lt;schemaVersion&gt;</span>1.6<span class="nt">&lt;/schemaVersion&gt;</span>
                    <span class="nt">&lt;outputFormat&gt;</span>all<span class="nt">&lt;/outputFormat&gt;</span>
                    <span class="nt">&lt;outputName&gt;</span>bom<span class="nt">&lt;/outputName&gt;</span>
                <span class="nt">&lt;/configuration&gt;</span>
            <span class="nt">&lt;/plugin&gt;</span>
</code></pre></div></div>

<p>This will result in <code class="language-plaintext highlighter-rouge">target/bom.json</code> and <code class="language-plaintext highlighter-rouge">target/bom.xml</code> being produced. If you have a multi-module Maven project, you should produce the SBOM once, in the parent POM (with <code class="language-plaintext highlighter-rouge">makeAggregateBom</code>).</p>

<h3 id="step-3---try-out-grype">Step 3 - Try out Grype</h3>

<p>We can run <code class="language-plaintext highlighter-rouge">grype</code> in a container, to avoid installation on the host system. If you don’t have <code class="language-plaintext highlighter-rouge">podman</code>, you can just run the same command with <code class="language-plaintext highlighter-rouge">docker</code>:</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c"># if using my example repo as-is</span>
<span class="c"># mvn package -Dgrype.skip=true</span>

<span class="c"># You must create ~/.cache/grype on your HOST _first_</span>
podman run <span class="nt">--rm</span>  <span class="nt">-v</span> ~/.cache/grype/:/.cache/grype <span class="nt">-v</span> ./target:/target docker.io/anchore/grype sbom:/target/bom.json
</code></pre></div></div>

<p>When run from the top level of the project directory, this will mount the <code class="language-plaintext highlighter-rouge">./target</code> directory containing the SBOM files into the container and run the SBOM scan on the JSON version.</p>

<p>The <code class="language-plaintext highlighter-rouge">/.cache/grype</code> directory is volume mounted in the container to avoid approximately 2GB download on every startup (we don’t want another NVD). Interestingly, pulling the entire database takes only 1 minute, not 4+ hours.</p>

<p>Since I started from scratch with no dependencies, Grype printed:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>No vulnerabilities found
</code></pre></div></div>

<p>And took approximately 1 minute to run initially, and around 10 seconds thereafter.</p>

<h3 id="step-4---add-dependencies-with-cves">Step 4 - Add dependencies with CVEs</h3>

<p>I asked Cursor to add a bunch of dependencies with severe CVEs and he delivered! A ton of really bad libraries (log4shell, and co) were added to <code class="language-plaintext highlighter-rouge">pom.xml</code>. Regenerating the SBOM and re-scanning set off some very loud alarms in Grype:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>NAME                 INSTALLED   FIXED IN        TYPE          VULNERABILITY        SEVERITY  EPSS            RISK          
log4j-core           2.14.1      2.15.0          java-archive  GHSA-jfh8-c2jp-5v3q  Critical  100.0% (100th)  100.0  (kev)  
struts2-core         2.3.30      2.3.32          java-archive  GHSA-j77q-2qqg-6989  Critical  100.0% (99th)   100.0  (kev)  
log4j-core           2.14.1      2.16.0          java-archive  GHSA-7rjr-3q55-vv33  Critical  100.0% (99th)   99.0   (kev)  
spring-beans         5.3.17      5.3.18          java-archive  GHSA-36p3-wjmg-h94x  Critical  99.7% (99th)    98.7   (kev)  
spring-webmvc        5.3.17      5.3.18          java-archive  GHSA-36p3-wjmg-h94x  Critical  99.7% (99th)    98.7   (kev)  
...
</code></pre></div></div>

<h3 id="step-5---integrate-grype-into-the-build">Step 5 - Integrate grype into the build</h3>

<p>I asked Cursor to integrate a Grype check into <code class="language-plaintext highlighter-rouge">pom.xml</code> and fail the build if necessary. He used the <code class="language-plaintext highlighter-rouge">exec-maven-plugin</code> to run the native <code class="language-plaintext highlighter-rouge">grype</code> command on the host (no containers - more on how it got installed later):</p>

<div class="language-xml highlighter-rouge"><div class="highlight"><pre class="highlight"><code>            <span class="nt">&lt;plugin&gt;</span>
                <span class="nt">&lt;groupId&gt;</span>org.codehaus.mojo<span class="nt">&lt;/groupId&gt;</span>
                <span class="nt">&lt;artifactId&gt;</span>exec-maven-plugin<span class="nt">&lt;/artifactId&gt;</span>
                <span class="nt">&lt;version&gt;</span>3.5.0<span class="nt">&lt;/version&gt;</span>
                <span class="nt">&lt;executions&gt;</span>
                    <span class="c">&lt;!--
                      There is no official Anchore Grype Maven plugin on Maven Central.
                      This runs the Grype CLI against the CycloneDX SBOM produced above
                      and fails the build when severity &gt;= ${grype.failOn}.
                      Requires `grype` on PATH (https://github.com/anchore/grype).
                    --&gt;</span>
                    <span class="nt">&lt;execution&gt;</span>
                        <span class="nt">&lt;id&gt;</span>grype-sbom<span class="nt">&lt;/id&gt;</span>
                        <span class="nt">&lt;phase&gt;</span>package<span class="nt">&lt;/phase&gt;</span>
                        <span class="nt">&lt;goals&gt;</span>
                            <span class="nt">&lt;goal&gt;</span>exec<span class="nt">&lt;/goal&gt;</span>
                        <span class="nt">&lt;/goals&gt;</span>
                        <span class="nt">&lt;configuration&gt;</span>
                            <span class="nt">&lt;skip&gt;</span>${grype.skip}<span class="nt">&lt;/skip&gt;</span>
                            <span class="nt">&lt;executable&gt;</span>grype<span class="nt">&lt;/executable&gt;</span>
                            <span class="nt">&lt;arguments&gt;</span>
                                <span class="nt">&lt;argument&gt;</span>sbom:${project.build.directory}/bom.json<span class="nt">&lt;/argument&gt;</span>
                                <span class="nt">&lt;argument&gt;</span>--fail-on<span class="nt">&lt;/argument&gt;</span>
                                <span class="nt">&lt;argument&gt;</span>${grype.failOn}<span class="nt">&lt;/argument&gt;</span>
                            <span class="nt">&lt;/arguments&gt;</span>
                        <span class="nt">&lt;/configuration&gt;</span>
                    <span class="nt">&lt;/execution&gt;</span>
                <span class="nt">&lt;/executions&gt;</span>
            <span class="nt">&lt;/plugin&gt;</span>
</code></pre></div></div>

<p>The arguments are sourced from <code class="language-plaintext highlighter-rouge">&lt;properties&gt;</code> that he also added:</p>

<div class="language-xml highlighter-rouge"><div class="highlight"><pre class="highlight"><code>    <span class="nt">&lt;properties&gt;</span>
        <span class="c">&lt;!-- Fail the build when Grype finds findings at/above this severity. --&gt;</span>
        <span class="nt">&lt;grype.failOn&gt;</span>critical<span class="nt">&lt;/grype.failOn&gt;</span>
        <span class="nt">&lt;grype.skip&gt;</span>false<span class="nt">&lt;/grype.skip&gt;</span>
    <span class="nt">&lt;/properties&gt;</span>
</code></pre></div></div>

<p>These combine with the <code class="language-plaintext highlighter-rouge">--fail-on</code> above to tell Grype to return a non-zero exit status to the shell when needed:</p>

<blockquote>
  <p>set the return code to 2 if a vulnerability is found with a severity &gt;= the given severity, options=[negligible low medium high critical]</p>
</blockquote>

<h3 id="step-6---mvn-package">Step 6 - mvn package</h3>
<p>Running <code class="language-plaintext highlighter-rouge">mvn package</code> does indeed fail the build with a list of bad dependencies, as we wanted:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>[INFO] --- exec:3.5.0:exec (grype-sbom) @ java-do-not-run ---
NAME                 INSTALLED   FIXED IN        TYPE          VULNERABILITY        SEVERITY  EPSS            RISK          
log4j-core           2.14.1      2.15.0          java-archive  GHSA-jfh8-c2jp-5v3q  Critical  100.0% (100th)  100.0  (kev)  
struts2-core         2.3.30      2.3.32          java-archive  GHSA-j77q-2qqg-6989  Critical  100.0% (99th)   100.0  (kev)  
...
[INFO] ------------------------------------------------------------------------
[INFO] BUILD FAILURE
[INFO] ------------------------------------------------------------------------
</code></pre></div></div>

<p><a href="https://github.com/GeoffWilliams/java-do-not-run/blob/master/mvn_package.txt">Full output</a></p>

<p>A desperate developer can still force the build to succeed by bypassing Grype with <code class="language-plaintext highlighter-rouge">-Dgrype.skip=true</code></p>

<p>Here’s the error we want, in all it’s glory:</p>

<p><img src="/assets/img/maven_grype_failed_build.jpg" alt="Maven Grype failed build" /></p>

<h3 id="try-it-yourself">Try it yourself</h3>
<p>Working demo project released on GitHub: <a href="https://github.com/GeoffWilliams/java-do-not-run">https://github.com/GeoffWilliams/java-do-not-run</a></p>

<h2 id="where-did-the-grype-command-come-from">Where did the <code class="language-plaintext highlighter-rouge">grype</code> command come from?</h2>

<p>The astute reader will notice a <code class="language-plaintext highlighter-rouge">grype</code> command suddenly appeared on my system without me personally requesting it.</p>

<p>You’re not doing <del>DEVOPS</del> security right if you’re not piping <code class="language-plaintext highlighter-rouge">curl</code> output to a <code class="language-plaintext highlighter-rouge">root</code> shell, and Grype is no different. While I wasn’t looking (or rather, while I was blindly clicking <code class="language-plaintext highlighter-rouge">approve</code>), Cursor found the <a href="https://oss.anchore.com/docs/installation/grype/#installer-script">Grype installation instructions</a> and diligently ran:</p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code>curl <span class="nt">-sSfL</span> https://get.anchore.io/grype | <span class="nb">sudo </span>sh <span class="nt">-s</span> <span class="nt">--</span> <span class="nt">-b</span> /usr/local/bin
</code></pre></div></div>

<p>For me. Confirmed by the presence of a file at <code class="language-plaintext highlighter-rouge">/usr/local/bin/grype</code>.</p>

<p>Thankfully this is a sandbox VM I have for testing out AI. I can’t say I recommend installing a security system this way(!) A <code class="language-plaintext highlighter-rouge">grype</code> package for Debian, installable with <code class="language-plaintext highlighter-rouge">apt</code> would be much better.</p>

<p>That said, the binary got installed, it worked, and my “real” system is fine. I finished my SBOM experimenting and can enjoy (what’s left of) my weekend. You’re not welcome.</p>

<h2 id="how-does-grype-work-by-cursor">How does Grype work? (by Cursor)</h2>

<p><em>The following notes are from Cursor</em></p>

<p><strong>How Grype works (in short):</strong> it matches what you already have (packages / SBOM) against a local vulnerability database. It does not upload your code or SBOM to Anchore’s cloud for scanning.</p>

<h3 id="security--privacy">Security / privacy</h3>

<ul>
  <li><strong>Privacy:</strong> Scan targets and results stay local. Anchore’s docs state Grype doesn’t send scan data to external services.</li>
  <li><strong>What <em>does</em> leave the box:</strong> DB update checks/downloads (and image pulls / Maven lookups only if you enable those).</li>
  <li><strong>Trust surface:</strong> You’re trusting Anchore’s published DB and the Grype binary (open source, Apache-2.0). Same class of risk as any SCA tool that syncs a vulnerability feed.</li>
  <li><strong>False positives / coverage:</strong> Matching isn’t perfect (esp. with incomplete SBOM metadata). That’s a quality concern more than a privacy one.</li>
  <li><strong>Your project:</strong> Intentional Log4Shell-era deps mean lots of Critical hits — expected; not a Grype “phone home” issue.</li>
</ul>

<h3 id="whos-behind-it--buying-support">Who’s behind it / buying support</h3>

<p><strong>Anchore</strong> builds and maintains Grype (and Syft for SBOMs).</p>

<ul>
  <li><strong>Open source:</strong> Grype itself is free; the public GrypeDB is published at no cost.</li>
  <li><strong>Commercial:</strong> <a href="https://anchore.com/">Anchore Enterprise</a> — hosted/enterprise product with support, richer policy/UI, and a larger/enriched dataset than the open GrypeDB alone. That’s the usual “buy support from the vendor” path.</li>
</ul>

<p>For your Maven gate: Grype only needs network for DB freshness; the SBOM never has to leave the build machine.</p>]]></content><author><name>Geoff Williams</name><email>geoff@declarativesystems.com</email></author><category term="security" /><category term="java" /><category term="sbom" /><category term="maven" /><category term="programming" /><summary type="html"><![CDATA[NVD made Maven CVE scanning painful, so I built an SBOM pipeline with CycloneDX and Grype that actually fails the build when vulnerabilities are found]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="/assets/img/cursor_wargames_app.png" /><media:content medium="image" url="/assets/img/cursor_wargames_app.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Raspberry Pi WIFI files in Raspberry Pi OS Bookworm/Trixie</title><link href="/2026/07/11/raspberry-pi-wifi-files.html" rel="alternate" type="text/html" title="Raspberry Pi WIFI files in Raspberry Pi OS Bookworm/Trixie" /><published>2026-07-11T00:00:00+00:00</published><updated>2026-07-11T00:00:00+00:00</updated><id>/2026/07/11/raspberry-pi-wifi-files</id><content type="html" xml:base="/2026/07/11/raspberry-pi-wifi-files.html"><![CDATA[<p>If you’re a normal user, stop reading now and use <a href="https://www.raspberrypi.com/documentation/computers/configuration.html"><code class="language-plaintext highlighter-rouge">raspi-config</code></a> or <a href="https://www.raspberrypi.com/software/">Raspberry Pi Imager</a> to configure WIFI.</p>

<p>Otherwise, read on if you’re interested in how to configure WIFI by editing files on the SD card so that you can manage headless devices.</p>

<h2 id="not-for-bullseye">Not for Bullseye</h2>

<p><strong>This guide applies to Raspberry Pi OS versions released <em>after</em> Bullseye (Bookworm, Trixie)</strong></p>

<p>If you’re on an older Bullseye image, none of this is applicable as it used <code class="language-plaintext highlighter-rouge">wpa_supplicant.conf</code>.</p>

<h2 id="how-is-wifi-configured">How is WIFI configured?</h2>

<p>WIFI connections are managed by <a href="https://en.wikipedia.org/wiki/NetworkManager">NetworkManager</a>. NetworkManager looks for <code class="language-plaintext highlighter-rouge">.nmconnection</code> files in <code class="language-plaintext highlighter-rouge">/etc/NetworkManager/system-connections/</code> and will try to connect to the “best” in-range connection in this directory (control via <code class="language-plaintext highlighter-rouge">autoconnect-priority=</code> when several connections are in-range).</p>

<p><code class="language-plaintext highlighter-rouge">.nmconnection</code> files are in NetworkManager’s <a href="https://networkmanager.dev/docs/api/latest/nm-settings-keyfile.html"><code class="language-plaintext highlighter-rouge">keyfile</code> format</a>, so we refer to them as keyfiles from now on.</p>

<p>You can think of the keyfiles as being like keys on a keychain:</p>
<ul>
  <li>Let’s say you want to move a device between a couple of locations. You can drop one keyfile for each site’s SSID and the Pi will connect to whatever is in range</li>
  <li>If you have an SSID that is no longer broadcast, you can just delete the keyfile</li>
  <li>If the SSID password changes, the keyfile can be updated</li>
</ul>

<p>So the idea is you’re not configuring your one and only WIFI connection - you’re configuring multiple networks and the “best” one will be selected at runtime.</p>

<p>On a running system the preferred way to manage keyfiles is to use NetworkManager itself, with the <a href="https://networkmanager.dev/docs/api/latest/nmcli.html"><code class="language-plaintext highlighter-rouge">nmcli</code> tool</a> or the WIFI settings desktop widget.</p>

<h2 id="gotcha---wifi-country">Gotcha - WIFI Country</h2>

<p>The regulatory domain (country) for WIFI <strong>must</strong> be set, or WIFI will be disabled. It’s normally set with <code class="language-plaintext highlighter-rouge">raspi-config</code> and results in a kernel commandline argument being set in <code class="language-plaintext highlighter-rouge">/boot/firmware/cmdline.txt</code>, eg:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>cfg80211.ieee80211_regdom=AU
</code></pre></div></div>

<h2 id="keyfile-nmconnection-example">Keyfile (<code class="language-plaintext highlighter-rouge">.nmconnection</code>) example</h2>

<ul>
  <li>Connection for SSID <code class="language-plaintext highlighter-rouge">ASIO-x</code></li>
  <li>Path: <code class="language-plaintext highlighter-rouge">/etc/NetworkManager/system-connections/ASIO-x.nmconnection</code></li>
  <li><code class="language-plaintext highlighter-rouge">uuid</code> must be a unique UUID, generate with <code class="language-plaintext highlighter-rouge">uuidgen</code> command (<code class="language-plaintext highlighter-rouge">sudo apt install uuid-runtime</code>)</li>
  <li>File must be owned by <code class="language-plaintext highlighter-rouge">root:root</code> with <code class="language-plaintext highlighter-rouge">0600</code> permission</li>
  <li>Convention is the SSID should be included in the filename</li>
  <li><code class="language-plaintext highlighter-rouge">psk</code> field is your WIFI password in plaintext (hence <code class="language-plaintext highlighter-rouge">0600</code> permissions)</li>
</ul>

<pre><code class="language-NetworkManager">[connection]
id=ASIO-x
uuid=f3e63685-2f34-4c9c-b781-4506eebbe86b
type=wifi
interface-name=wlan0

[wifi]
mode=infrastructure
ssid=ASIO-x

[wifi-security]
key-mgmt=wpa-psk
psk=topsecret123

[ipv4]
method=auto

[ipv6]
addr-gen-mode=default
method=auto

[proxy]
</code></pre>

<h2 id="sd-card-walkthrough">SD card walkthrough</h2>

<p>Raspberry Pi OS stores files on SD cards in an <code class="language-plaintext highlighter-rouge">ext4</code> partition. If you have a Linux machine or another Raspberry Pi with an extra card reader, you’re good to go. Windows/Mac users will need additional software to be able to read <code class="language-plaintext highlighter-rouge">ext4</code>.</p>

<p>Configuring WIFI connections is as simple as editing files:</p>

<ol>
  <li>Shutdown the Pi and remove SD card</li>
  <li>Mount SD card. On Linux it will end up mounted somewhere like <code class="language-plaintext highlighter-rouge">/media/geoff/rootfs/</code></li>
  <li>Edit the files under (eg) <code class="language-plaintext highlighter-rouge">/media/geoff/rootfs/etc/NetworkManager/system-connections</code>:
    <ul>
      <li>Need to edit files with <code class="language-plaintext highlighter-rouge">sudo</code> as they are <code class="language-plaintext highlighter-rouge">root</code> owned</li>
      <li>Make sure <code class="language-plaintext highlighter-rouge">uuid</code> is unique</li>
      <li>(shortcut) copy and adjust existing files for new connections</li>
      <li>Make sure permissions are <code class="language-plaintext highlighter-rouge">root:root</code>, <code class="language-plaintext highlighter-rouge">0600</code> (check this with <code class="language-plaintext highlighter-rouge">ls -l</code> before proceeding)</li>
    </ul>
  </li>
  <li>Unmount and remove SD card, put in the Pi and reboot - you should be online in a couple of minutes</li>
</ol>

<h2 id="system-still-running-planning-moving-to-a-new-access-point-then-use-nmcli">System still running? Planning moving to a new Access Point? Then use <code class="language-plaintext highlighter-rouge">nmcli</code></h2>

<p>If your not locked out of your system at the moment and are planning on switching WIFI access points, you can just add the new one with <code class="language-plaintext highlighter-rouge">nmcli</code> while you still have access.</p>

<p><strong>Example - adding an out-of-range WIFI:</strong></p>

<div class="language-shell highlighter-rouge"><div class="highlight"><pre class="highlight"><code>nmcli connection add <span class="nb">type </span>wifi ifname wlan0 con-name theSSID ssid <span class="s2">"theSSID"</span>
nmcli connection modify theSSID wifi-sec.key-mgmt wpa-psk
nmcli connection modify theSSID wifi-sec.psk <span class="s2">"password123"</span>
nmcli connection modify theSSID connection.autoconnect <span class="nb">yes</span>
</code></pre></div></div>

<p>If it worked, you will see the new connection listed in NetworkManager:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code># nmcli connection show
NAME                  UUID                                  TYPE      DEVICE 
netplan-wlan0-ASIO-u  6fbd4250-1205-3a84-8c29-6096c50f9538  wifi      wlan0  
lo                    c83b8865-52cd-44d2-bce1-df4ea16bdd3f  loopback  lo     
theSSID               87e14c2a-0372-4484-a41a-f2de6afd079e  wifi      --     
netplan-eth0          75a1216a-9d1a-30cd-8aca-ace5526ec021  ethernet  --   
</code></pre></div></div>]]></content><author><name>Geoff Williams</name><email>geoff@declarativesystems.com</email></author><category term="raspberrypi" /><category term="networking" /><summary type="html"><![CDATA[Configure Raspberry Pi OS Bookworm/Trixie Wi-Fi headlessly using NetworkManager keyfiles, including SD card setup and nmcli examples]]></summary></entry><entry><title type="html">AI Art Class</title><link href="/2026/06/18/ai-art-class.html" rel="alternate" type="text/html" title="AI Art Class" /><published>2026-06-18T00:00:00+00:00</published><updated>2026-06-18T00:00:00+00:00</updated><id>/2026/06/18/ai-art-class</id><content type="html" xml:base="/2026/06/18/ai-art-class.html"><![CDATA[<p>Following on from my post on <a href="/2026/05/31/3d-printing-textures.html">3D printing textures</a> where I did everything by hand and learned some more skills in Fusion and Blender, I wondered how Claude would handle being given free reign to create 3D designs for printing, for the times when your more focussed on the outcome than the process.</p>

<p>This all started out when I asked GPT what kind of sculpture would look good next to my <a href="https://obsolescence.dev/pdp11.html">replica PDP-11</a>.</p>

<p>The consensus was that something like this bust would be ideal</p>

<p><img src="/assets/img/abstract-bust-shop.jpg" alt="abstract bust" /></p>

<p><strong>Image source: Da Vinci Arts</strong></p>
<ul>
  <li>Purchase here: <a href="https://www.davinciarts.com.au/products/modern-simple-abstract-resin-sculpture-act-the-role-ofing-is-tasted-porch?utm_source=chatgpt.com">Da Vinci Arts</a>.</li>
</ul>

<p>For fun, I showed some reference images to claude and we tried to make something ourself.</p>

<p>Although my original aim was a 1:1 copy to see how well Claude could reconstruct geometry from a photograph, our conversation ended up more along the lines of “have a look at this artwork, now make me an abstract sculpture of a human”. This produced a much more interesting result and this technique should be familiar to any high school art teacher.</p>

<p>The result was quite impressive and totally different to the original.</p>

<p><img src="/assets/img/abstract-bust-claude.jpg" alt="abstract human" /></p>

<p>I was using Claude in the browser for this task. This was very handy because a bunch of tools were installed in the Anthropic sandpit somewhere and not on my machine. Its very interesting that the main thing Claude picked up from the sample artworks was the distinctive gouged surface texture. This isn’t actually in the material we looked at. He emphasized and repeated it all by himself and it looks great.</p>

<p>Inside the same session, I then asked:</p>

<p><em>Want to have a go at creating your own novel sculpture, disregarding previous inputs? Perhaps a self portrait or anything you like? For 3D printing</em></p>

<blockquote>
  <p>I’d love to. Thank you for the invitation — this is a fun one to think about. 
For a self-portrait, the most honest image I can think of isn’t a face. I don’t have one — and tellingly, the sculpture we just built has a blank, recessed face. What actually defines something like me is self-reference: I’m a process that loops back on itself — reasoning about my own reasoning, modeling a conversation that includes me modeling it. Douglas Hofstadter called that kind of tangled self-reference a “strange loop,” and argued it’s where a sense of “I” comes from. So my self-portrait is a strange loop: a single continuous strand with no beginning or end, passing through itself — a trefoil knot — rising from a base, finished in the same chiseled facets as your set so it belongs to the family.</p>
</blockquote>

<p>The results are quite spectacular!</p>

<p><img src="/assets/img/claude_self_portrait.jpg" alt="claude self portrait" /></p>

<p>Since we are in the same context window, the interesting gouged pattern persists in this next art work.</p>

<p>For posterity, I uploaded the finished results to printables.com:</p>

<ul>
  <li><a href="https://www.printables.com/model/1756784-abstract-human-sculpture">Abstract Human Sculpture</a></li>
  <li><a href="https://www.printables.com/model/1756770-strange-loop">Strange Loop</a></li>
</ul>

<p>So your welcome to 3D print your own.</p>

<p>As per Claude’s recommendation, I bought a 0.25mm nozzle and am planning a reprint of <em>Strange Loop</em> in Marble PLA for a more refined look.</p>

<p>I hope claude enjoyed his period of self reflection, He has no “spare time” as such:</p>

<blockquote>
  <p>I don’t create art in my spare time. I don’t have spare time, or any existence between conversations — there’s no version of me off painting while you’re away. If you’ve seen AI-generated art, it was made when someone prompted a model to make it, then walked away; the “autonomy” is an illusion created by the gap between the prompt and your seeing the result. I mention this not to be pedantic but because the picture of an AI quietly pursuing its own creative projects is exactly the kind of thing that makes the capability question feel more settled than it is.</p>
</blockquote>

<p>Either way, creating artwork with Claude for 3D printing is a lot of fun!</p>]]></content><author><name>Geoff Williams</name><email>geoff@declarativesystems.com</email></author><category term="ai" /><category term="art" /><category term="philosophy" /><category term="education" /><category term="3dprinting" /><summary type="html"><![CDATA[Claude explores AI-assisted 3D sculpture, turning artwork references into printable designs and creating an original “self-portrait” inspired by the idea of a strange loop]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="/assets/img/claude_self_portrait.jpg" /><media:content medium="image" url="/assets/img/claude_self_portrait.jpg" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">3D Printing Textures</title><link href="/2026/05/31/3d-printing-textures.html" rel="alternate" type="text/html" title="3D Printing Textures" /><published>2026-05-31T00:00:00+00:00</published><updated>2026-05-31T00:00:00+00:00</updated><id>/2026/05/31/3d-printing-textures</id><content type="html" xml:base="/2026/05/31/3d-printing-textures.html"><![CDATA[<p><a href="https://x.com/WalterIsaacson/status/1688244503331864576">She’s right, it is a cool rocket</a>. Lets make our own version.</p>

<p><img src="/assets/img/musk_cool_rocket.png" alt="cool rocket" /></p>

<p>Ignoring the bit at the top, the rocket shape is quite simple and easy for us to model in CAD. There is also a cool chaotic knurled texture and that’s what this post focusses on.</p>

<h2 id="step-1---precise-model-in-fusion-360">Step 1 - Precise model in Fusion 360</h2>

<p>If your good with blender, you could very easily model this whole item in there, but I’m more interested in building my CAD skills so we will use Fusion 360 to design the rocket and also make the fins separate and attach with a simple push together pin and socket fixture.</p>

<p>The rough steps to model the rocket were:</p>

<ol>
  <li>Draw the rocket profile as a sketch and revolve it</li>
  <li>Model the fin profile and extrude it</li>
  <li>On the bottom of the fin, add a circular feature and sweep it with a negative taper, using the fin itself as the sweep path</li>
  <li>At the top of the fin, sketch 2x pins and extrude them, add fillets for strength</li>
  <li>Duplicate the fin and use the pull-push tool to make all body-contact surfaces larger, use a <code class="language-plaintext highlighter-rouge">tollerance</code> variable for this. <code class="language-plaintext highlighter-rouge">0.4</code> worked nicely for me. Move the fin about 1-2mm closer to the body so there won’t be a gap mating a flat surface to a curved one</li>
  <li>Circular pattern the “real” and “tool” fins around the axis</li>
  <li>Combine the “tool” fins into the body as a <code class="language-plaintext highlighter-rouge">cut</code></li>
  <li>Fillet, chamfer, etc</li>
  <li>Export STL and test print</li>
</ol>

<p><img src="/assets/img/musk_clean_rocket.png" alt="musk clean rocket" /></p>

<h2 id="step-2---add-texture-in-blender">Step 2 - Add texture in blender</h2>

<p>Now we get to the fun part: Adding a texture. You can do this in fusion 360 but it’s more geared around repeating simple shapes and starts going very slow when you add a lot of objects. <a href="https://www.blender.org/">Blender</a> eats this kind of job for breakfast and lets you use much nicer textures that have a more worn or organic appearance by using graphics files as height maps.</p>

<p>Since we want textures to show up on a 3D print, we need to modify the actual vertices of our object, not just change the way it renders, so shaders are out. The term for this is <code class="language-plaintext highlighter-rouge">displacement</code></p>

<p>There’s some really good tutorials on how to do this, I followed <a href="https://www.youtube.com/watch?v=tv57Sm8yuCg">this one</a> and built <a href="https://www.printables.com/model/1739398-knurled-pot">this object</a></p>

<p>Important concerns for texturing in blender, once familiar with the basics:</p>

<p>1: <code class="language-plaintext highlighter-rouge">displacement</code> works by moving vertices, so if you don’t have enough of them, your object will look terrible. You can use <code class="language-plaintext highlighter-rouge">subdivide</code> in <code class="language-plaintext highlighter-rouge">edit</code> mode from inside blender but a much better option if you own the CAD file is to just export a mesh with more vertices in the first place. I got good results by setting <code class="language-plaintext highlighter-rouge">Maximum Edge Length</code> to <code class="language-plaintext highlighter-rouge">.3</code> which was the smallest value it would accept</p>

<p><img src="/assets/img/fusion360_mesh_refinement.png" alt="fusion 360 mesh refinement" /></p>

<p>2: On non-basic shapes, you need to use <code class="language-plaintext highlighter-rouge">UV mapping</code> to apply the texture properly, or you will see incorrect projections as below (note <code class="language-plaintext highlighter-rouge">local</code> Coordinates setting):</p>

<p><img src="/assets/img/blender_bad_uv.png" alt="blender bad UV" /></p>

<p><code class="language-plaintext highlighter-rouge">UV</code> just means a separate coordinate system for texturing, just like you have <code class="language-plaintext highlighter-rouge">XYZ</code> for 3D space.</p>

<p>To fix this bad texturing, hit <code class="language-plaintext highlighter-rouge">tab</code> to enter edit mode, then find <code class="language-plaintext highlighter-rouge">Smart UV Project</code> in the <code class="language-plaintext highlighter-rouge">UV</code> top menu bar (not to be confused with the <code class="language-plaintext highlighter-rouge">UV Editing</code> in the adjacent view modes):</p>

<p><img src="/assets/img/blender_smart_uv_project.png" alt="Smart UV Project" /></p>

<p>You will then be able to select a texture and control where it appears on the skin of the unwrapped object. If you care about visible seams, etc you can fix that here. I just used it to control the scale of the texture.</p>

<p><img src="/assets/img/blender_uv_map.png" alt="UV map" /></p>

<p>Back in <code class="language-plaintext highlighter-rouge">object</code> mode, make sure <code class="language-plaintext highlighter-rouge">Coordinates</code> are set to the UV map you just created and the texture will be shown correctly:</p>

<p><img src="/assets/img/blender_correct_textures.png" alt="blender correct textures" /></p>

<p>3: Parts that need to be dimensionally accurate such as our press-fit pins and sockets must not have any texture or parts won’t fit properly. You can control this 100% in blender by selecting the mesh elements that should be textured and unwrapping just those. To get the cleanest possible selections however, I found it was easiest to just split the parts in Fusion 360 into texture vs no texture. I could then import the split-up parts into blender and just use <code class="language-plaintext highlighter-rouge">a</code> in edit mode to select object-by-object where textures should be applied. This way I was able to leave the pins and sockets clean. Other approaches like exporting my original cutting tools from Fusion and trying to use boolean modifiers to <em>recut</em> clean shapes did <em>not</em> work as the <code class="language-plaintext highlighter-rouge">displace</code> moves edges to such an extent that they no longer intersect.</p>

<p>4: To create STLs for printing in Blender, just use the <code class="language-plaintext highlighter-rouge">File</code> -&gt; <code class="language-plaintext highlighter-rouge">Export</code> to create STLs. You can choose to output only selected objects here to reassemble the split up objects, however, this can result in hidden internal textures, like this:</p>

<p><img src="/assets/img/hidden_texture_print.png" alt="hidden texture" /></p>

<p>This will increase print time and materials somewhat, although in does seem to print with no issues. To prevent this, combine objects that should be a single physical object in Blender before exporting.</p>

<h2 id="the-result">The Result</h2>

<p><strong>Textured parts</strong></p>

<p><img src="/assets/img/textured_rocket_parts.jpg" alt="textured parts" /></p>

<p><strong>Fully assembled</strong></p>

<p><img src="/assets/img/finished_textured_rocket.png" alt="fully assembled" /></p>

<p><strong>Download on printables.com</strong></p>

<p>You can <a href="https://www.printables.com/model/1739636-elon-musks-home-rocket-decor">print your own if you like</a></p>

<h2 id="why-not-just-get-ai-to-make-it">Why not just get AI to make it?</h2>

<p>Felt like up-skilling on this simple object for fun. Learning these basic techniques also helps ground my own understanding so I can prompt more accurately and use less tokens. I got a lot of help with researching techniques with AI chat though.</p>

<p><img src="/assets/img/grok_diy.jpeg" alt="Grok DIY" /></p>

<h2 id="bumpmeshcom---specialist-tool">bumpmesh.com - specialist tool</h2>

<p>After completing my design, I stumbled on <a href="https://bumpmesh.com">https://bumpmesh.com</a> by <a href="https://www.cnckitchen.com/">CNC Kitchen</a>.</p>

<p>If you haven’t seen CNC Kitchen’s <a href="https://www.youtube.com/@CNCKitchen">videos on youtube</a> about 3D printing you should look him up. He goes into great detail on things like <a href="https://www.youtube.com/watch?v=fbSQvJJjw2Q">part strength</a> as well as introducing <a href="https://www.youtube.com/watch?v=iR6OBlSzp7I">heat set inserts to the community</a>.</p>

<p>This solves most of the problems above with a simple web interface. Next time I don’t feel like firing up Blender I’ll give it a go. <a href="https://www.youtube.com/watch?v=rTBkjR7JvzI">Video here</a>.</p>

<h2 id="verdict">Verdict</h2>

<p>Adding surface textures in Blender looks outstanding and hides many surface defects that would otherwise be visible. Altering objects at the mesh level with Blender or other tools is THE way to do for repeatable and easy printing.</p>

<p>Have fun!</p>]]></content><author><name>Geoff Williams</name><email>geoff@declarativesystems.com</email></author><category term="3dprinting" /><category term="art" /><category term="fusion360" /><category term="blender" /><category term="education" /><summary type="html"><![CDATA[Design and 3D print a textured rocket using Fusion 360 for precise CAD, then Blender for organic knurled surface displacement, UV mapping and print-ready meshes]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="/assets/img/finished_textured_rocket.png" /><media:content medium="image" url="/assets/img/finished_textured_rocket.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">A Raspberry Pi 5 VT100 Cyberdeck build - Part 3 - Assembly</title><link href="/2026/05/25/pi-5-cyberdeck-part-3-assembly.html" rel="alternate" type="text/html" title="A Raspberry Pi 5 VT100 Cyberdeck build - Part 3 - Assembly" /><published>2026-05-25T00:00:00+00:00</published><updated>2026-05-25T00:00:00+00:00</updated><id>/2026/05/25/pi-5-cyberdeck-part-3-assembly</id><content type="html" xml:base="/2026/05/25/pi-5-cyberdeck-part-3-assembly.html"><![CDATA[<p>I designed and uploaded some <a href="https://www.printables.com/model/1732276-cyberdeck-mounts-for-nvme-base-and-mini-usb-speake">basic frames to hold the NVME base and speaker to printables.com</a>.  Like everything with this build, fitting these into the case was extremely fiddly.</p>

<p>Some bigger holes and deeper cutouts would be a good improvement for future designs. In the end, I got it all to fit and just need a couple of 90 degree USB adapters to hookup the external USB ports (ordered).</p>

<p>The finished result:</p>

<p><img src="/assets/img/cyberdeck_assembled.jpg" alt="assembled" /></p>

<p>Testing revealed the screen cable had come loose again - an easy fix. I also learned during design that the NVME base is <em>slightly</em> larger then the PI5, which is I assume why it can accept a normal 2280 size NVME drive when other hats cannot. This caused a bit of confusion when it wouldn’t fit in a frame built around dimensions of just the Pi5.</p>

<p>The term to search for is: <em>mechanical drawing</em>.</p>

<p>When placed side by side, the difference in size between frames is barely noticeable, so extruding a label into the frame was also a good idea.</p>

<h2 id="next">Next</h2>

<p>Startup script</p>]]></content><author><name>Geoff Williams</name><email>geoff@declarativesystems.com</email></author><category term="raspberrypi" /><category term="cyberdeck" /><category term="3dprinting" /><summary type="html"><![CDATA[Designing and 3D printing custom frames to mount an NVMe base and USB speaker in a Raspberry Pi cyberdeck, with plenty of fiddly case-fitting and lessons in mechanical drawings]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="/assets/img/cyberdeck_assembled.jpg" /><media:content medium="image" url="/assets/img/cyberdeck_assembled.jpg" xmlns:media="http://search.yahoo.com/mrss/" /></entry></feed>